

SimScale: Learning to Drive via Real-World Simulation at Scale
Paper • 2511.23369 • Published • 39
Exception:    SplitsNotFoundError
Message:      The split names could not be parsed from the dataset config.
Traceback:    Traceback (most recent call last):
                File "/usr/local/lib/python3.14/site-packages/datasets/inspect.py", line 286, in get_dataset_config_info
                  for split_generator in builder._split_generators(
                                         ~~~~~~~~~~~~~~~~~~~~~~~~~^
                      StreamingDownloadManager(base_path=builder.base_path, download_config=download_config)
                      ^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^
                  )
                  ^
                File "/usr/local/lib/python3.14/site-packages/datasets/packaged_modules/webdataset/webdataset.py", line 81, in _split_generators
                  first_examples = list(islice(pipeline, self.NUM_EXAMPLES_FOR_FEATURES_INFERENCE))
                File "/usr/local/lib/python3.14/site-packages/datasets/packaged_modules/webdataset/webdataset.py", line 32, in _get_pipeline_from_tar
                  fs: fsspec.AbstractFileSystem = fsspec.filesystem("memory")
                                                  ~~~~~~~~~~~~~~~~~^^^^^^^^^^
                File "/usr/local/lib/python3.14/site-packages/fsspec/registry.py", line 302, in filesystem
                  cls = get_filesystem_class(protocol)
                File "/usr/local/lib/python3.14/site-packages/fsspec/registry.py", line 239, in get_filesystem_class
                  raise ValueError(f"Protocol not known: {protocol}")
              ValueError: Protocol not known: memory

              The above exception was the direct cause of the following exception:

              Traceback (most recent call last):
                File "/src/services/worker/src/worker/job_runners/config/split_names.py", line 71, in compute_split_names_from_streaming_response
                  for split in get_dataset_split_names(
                               ~~~~~~~~~~~~~~~~~~~~~~~^
                      path=dataset,
                      ^^^^^^^^^^^^^
                      config_name=config,
                      ^^^^^^^^^^^^^^^^^^^
                      token=hf_token,
                      ^^^^^^^^^^^^^^^
                  )
                  ^
                File "/usr/local/lib/python3.14/site-packages/datasets/inspect.py", line 340, in get_dataset_split_names
                  info = get_dataset_config_info(
                      path,
                  ...<6 lines>...
                      **config_kwargs,
                  )
                File "/usr/local/lib/python3.14/site-packages/datasets/inspect.py", line 291, in get_dataset_config_info
                  raise SplitsNotFoundError("The split names could not be parsed from the dataset config.") from err
              datasets.inspect.SplitsNotFoundError: The split names could not be parsed from the dataset config.
Need help to make the dataset viewer work? Make sure to review how to configure the dataset viewer, and open a discussion for direct support.


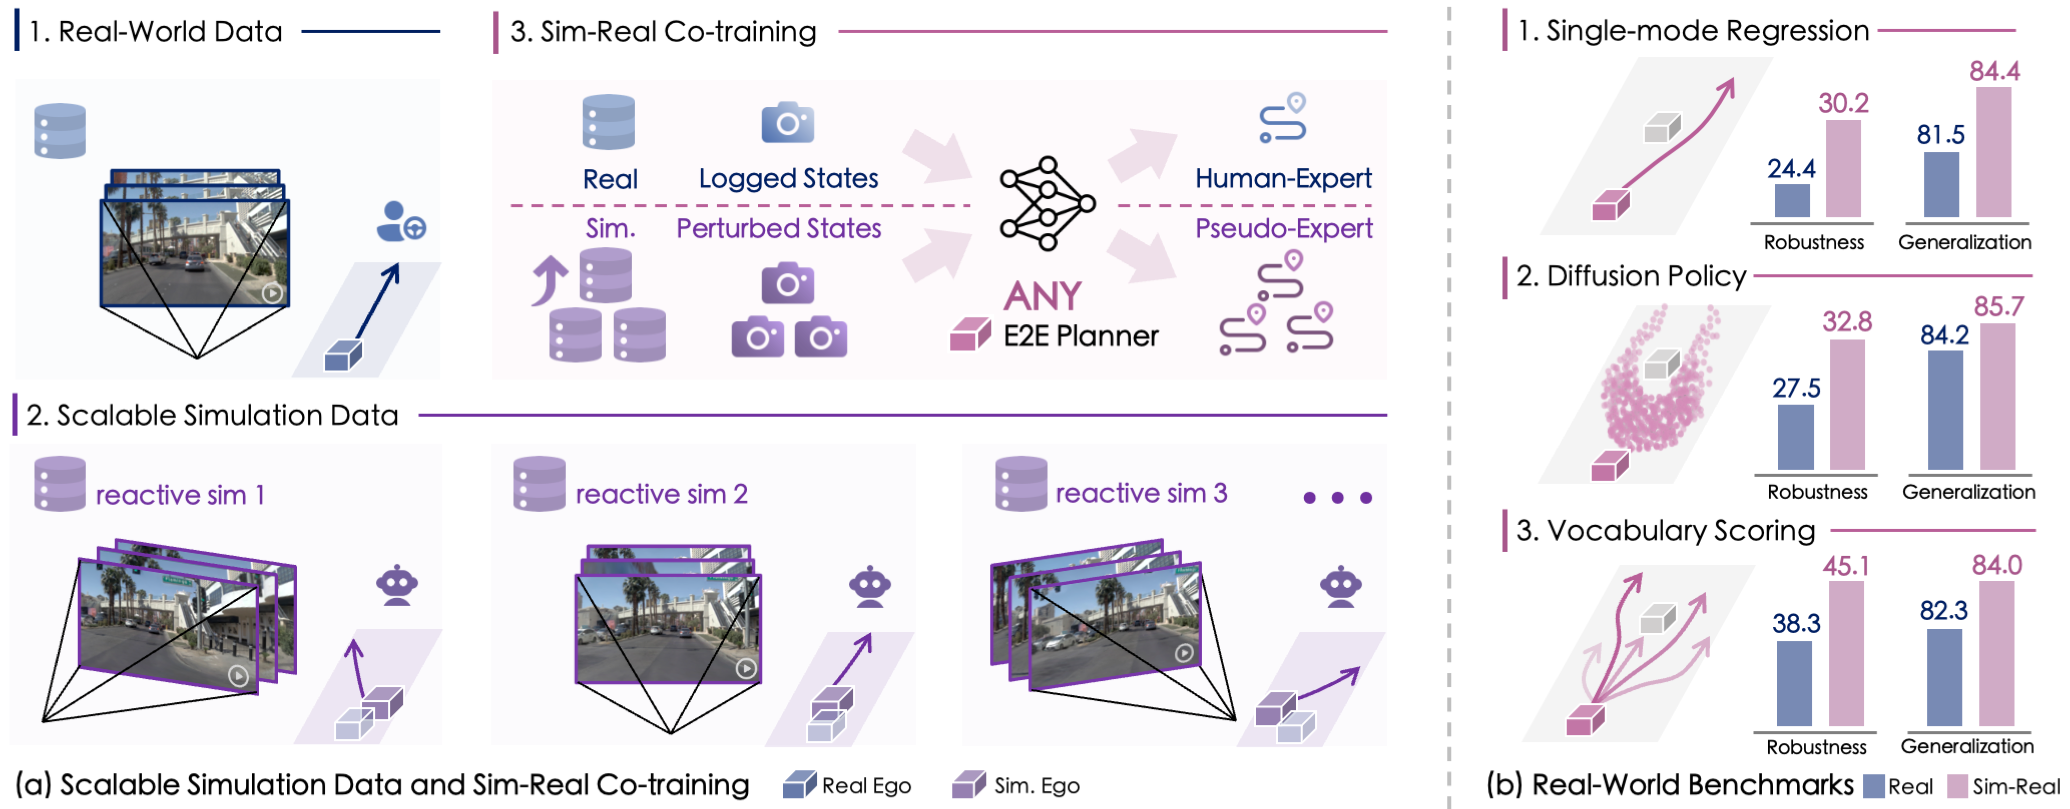
Haochen Tian, Tianyu Li, Haochen Liu, Jiazhi Yang, Yihang Qiu, Guang Li, Junli Wang, Yinfeng Gao, Zhang Zhang, Liang Wang, Hangjun Ye, Tieniu Tan, Long Chen, Hongyang Li
- 📧 Primary Contact: Haochen Tian (tianhaochen2023@ia.ac.cn)
- 📜 Materials: 🌐 𝕏 | 📰 Media | 🗂️ Slides | 🎬 Talk (in Chinese)
- 🖊️ Joint effort by CASIA, OpenDriveLab at HKU, and Xiaomi EV.
Our released simulation data is based on nuPlan and NAVSIM. We recommend first preparing the real-world data by following the instructions in Download NAVSIM. If you plan to use GTRS, please directly refer Download NAVSIM.
We provide 🤗 Script (Hugging Face) and 👾 Script (ModelScope) (users in China) for downloading the simulation data.
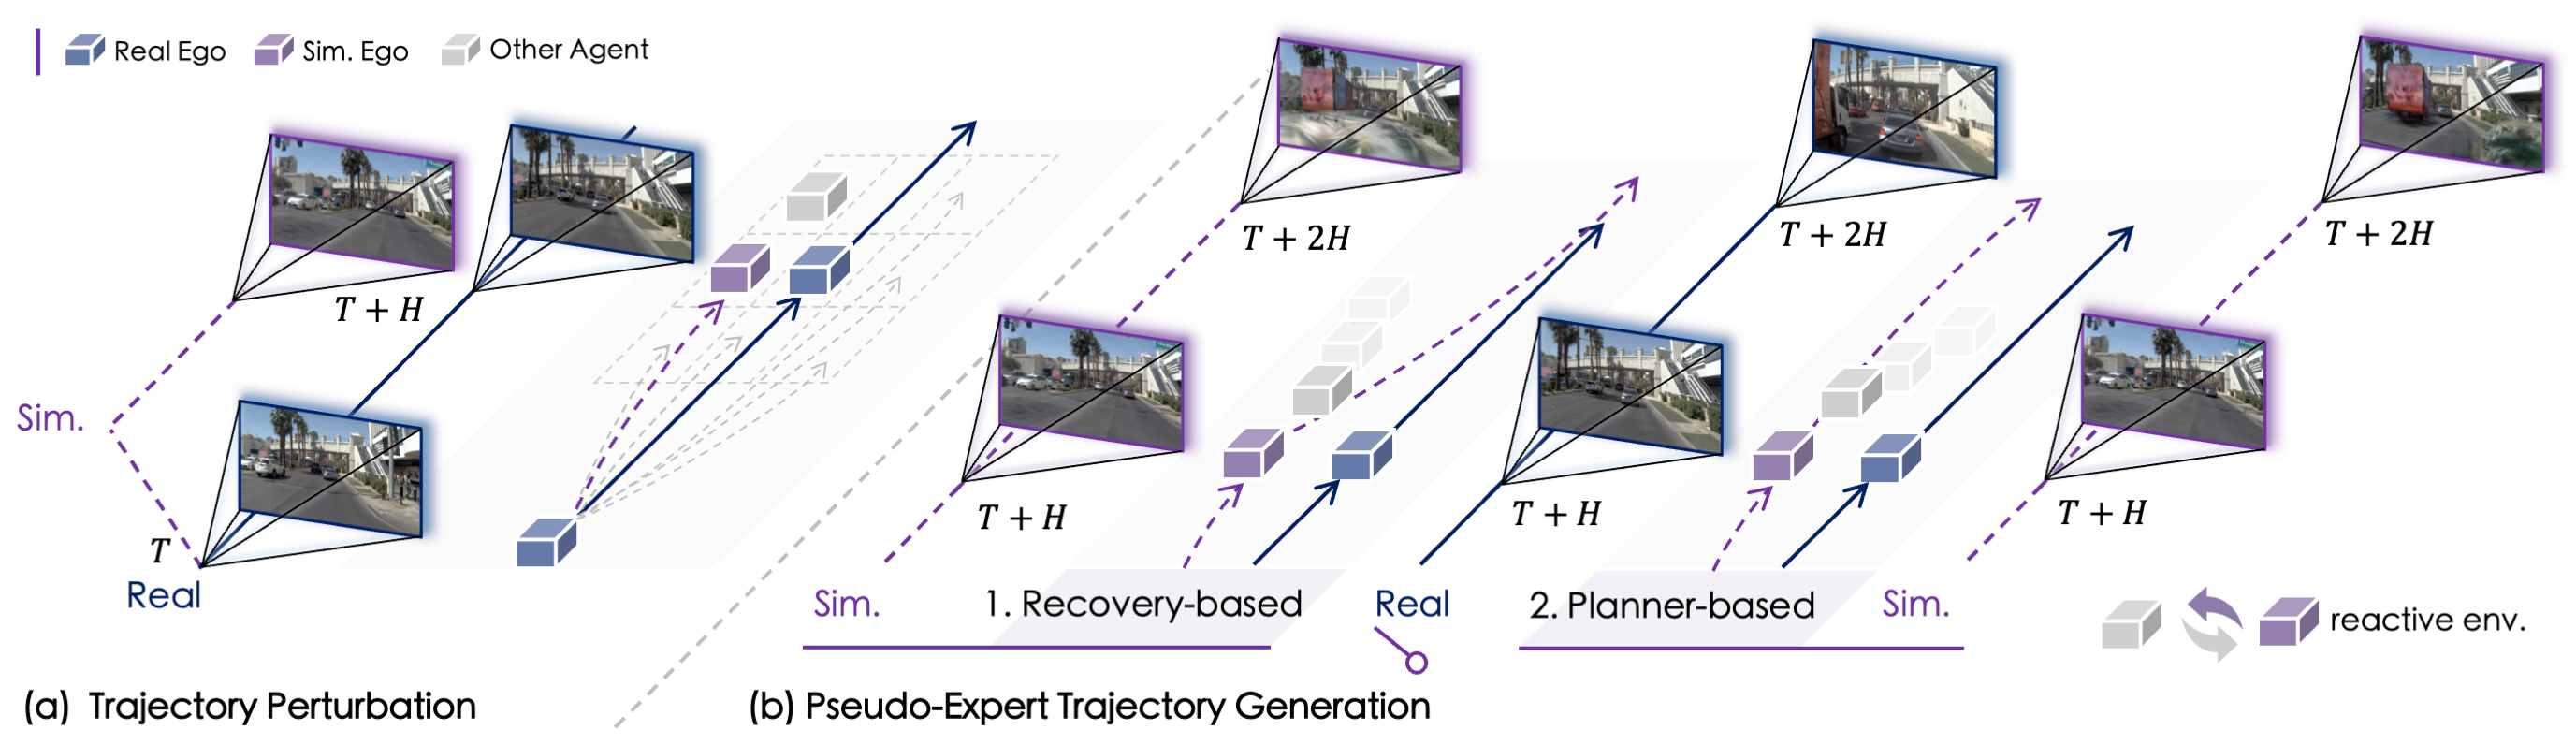
Our simulation data format follows that of OpenScene, with each clip/log has a fixed temporal horizon of 6 seconds at 2 Hz (2 s history + 4 s future), which are stored separately in sensor_blobs_hist and sensor_blobs_fut, respectively.
For policy training, sensor_blobs_hist alone is sufficient.
| Split / Sim. Round | # Tokens | Logs | Sensors_Hist | Sensors_Fut | Link |
|---|---|---|---|---|---|
| Planner-based Pseudo-Expert | |||||
| reaction_pdm_v1.0-0 | 65K | 9.9GB | 569GB | 1.2T | HF+ HF_Fut / MS |
| reaction_pdm_v1.0-1 | 55K | 8.5GB | 448GB | 964GB | HF+ HF_Fut / MS |
| reaction_pdm_v1.0-2 | 46K | 6.9GB | 402GB | 801GB | HF+ HF_Fut / MS |
| reaction_pdm_v1.0-3 | 38K | 5.6GB | 333GB | 663GB | HF+ HF_Fut / MS |
| reaction_pdm_v1.0-4 | 32K | 4.7GB | 279GB | 554GB | HF+ HF_Fut / MS |
| Recovery-based Pseudo-Expert | |||||
| reaction_recovery_v1.0-0 | 45K | 6.8GB | 395GB | 789GB | HF+ HF_Fut / MS |
| reaction_recovery_v1.0-1 | 36K | 5.5GB | 316GB | 631GB | HF+ HF_Fut / MS |
| reaction_recovery_v1.0-2 | 28K | 4.3GB | 244GB | 488GB | HF+ HF_Fut / MS |
| reaction_recovery_v1.0-3 | 22K | 3.3GB | 189GB | 378GB | HF+ HF_Fut / MS |
| reaction_recovery_v1.0-4 | 17K | 2.7GB | 148GB | 296GB | HF+ HF_Fut / MS |
Before downloading, we recommend checking the table above to select the appropriate split and
sensor_blobs.
|
5c9694f15f9c5537 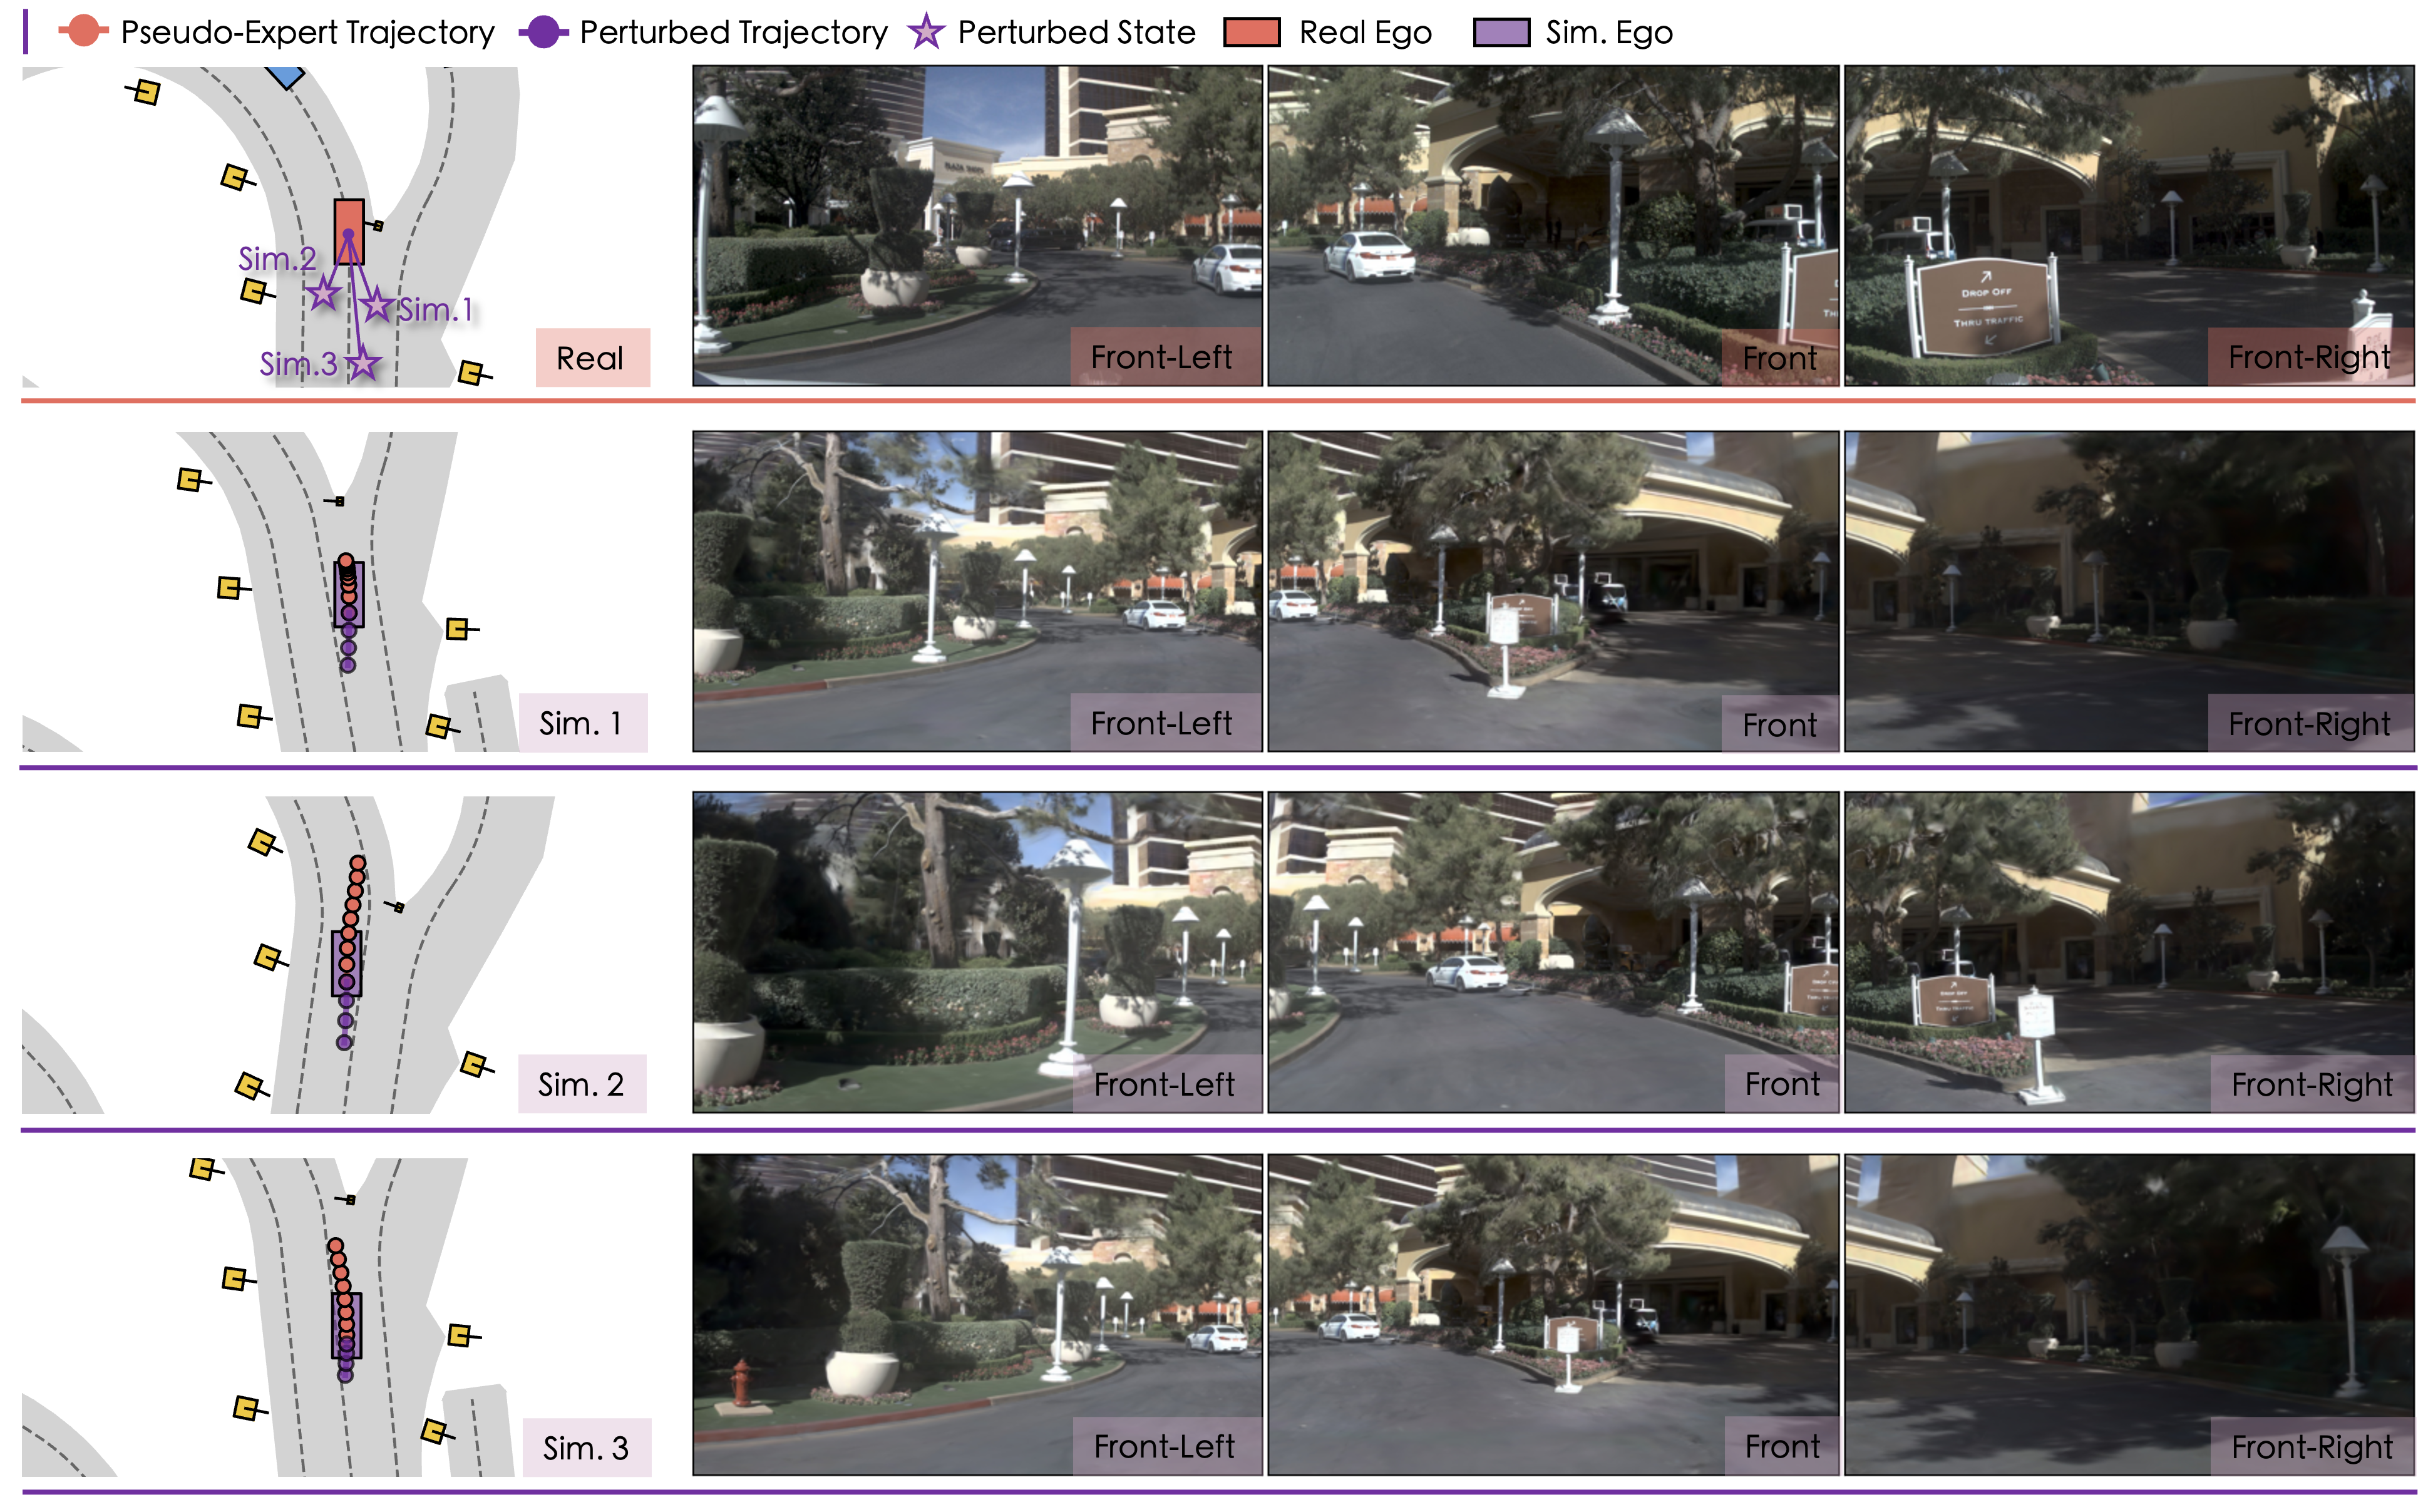
|
367cfa28901257ee 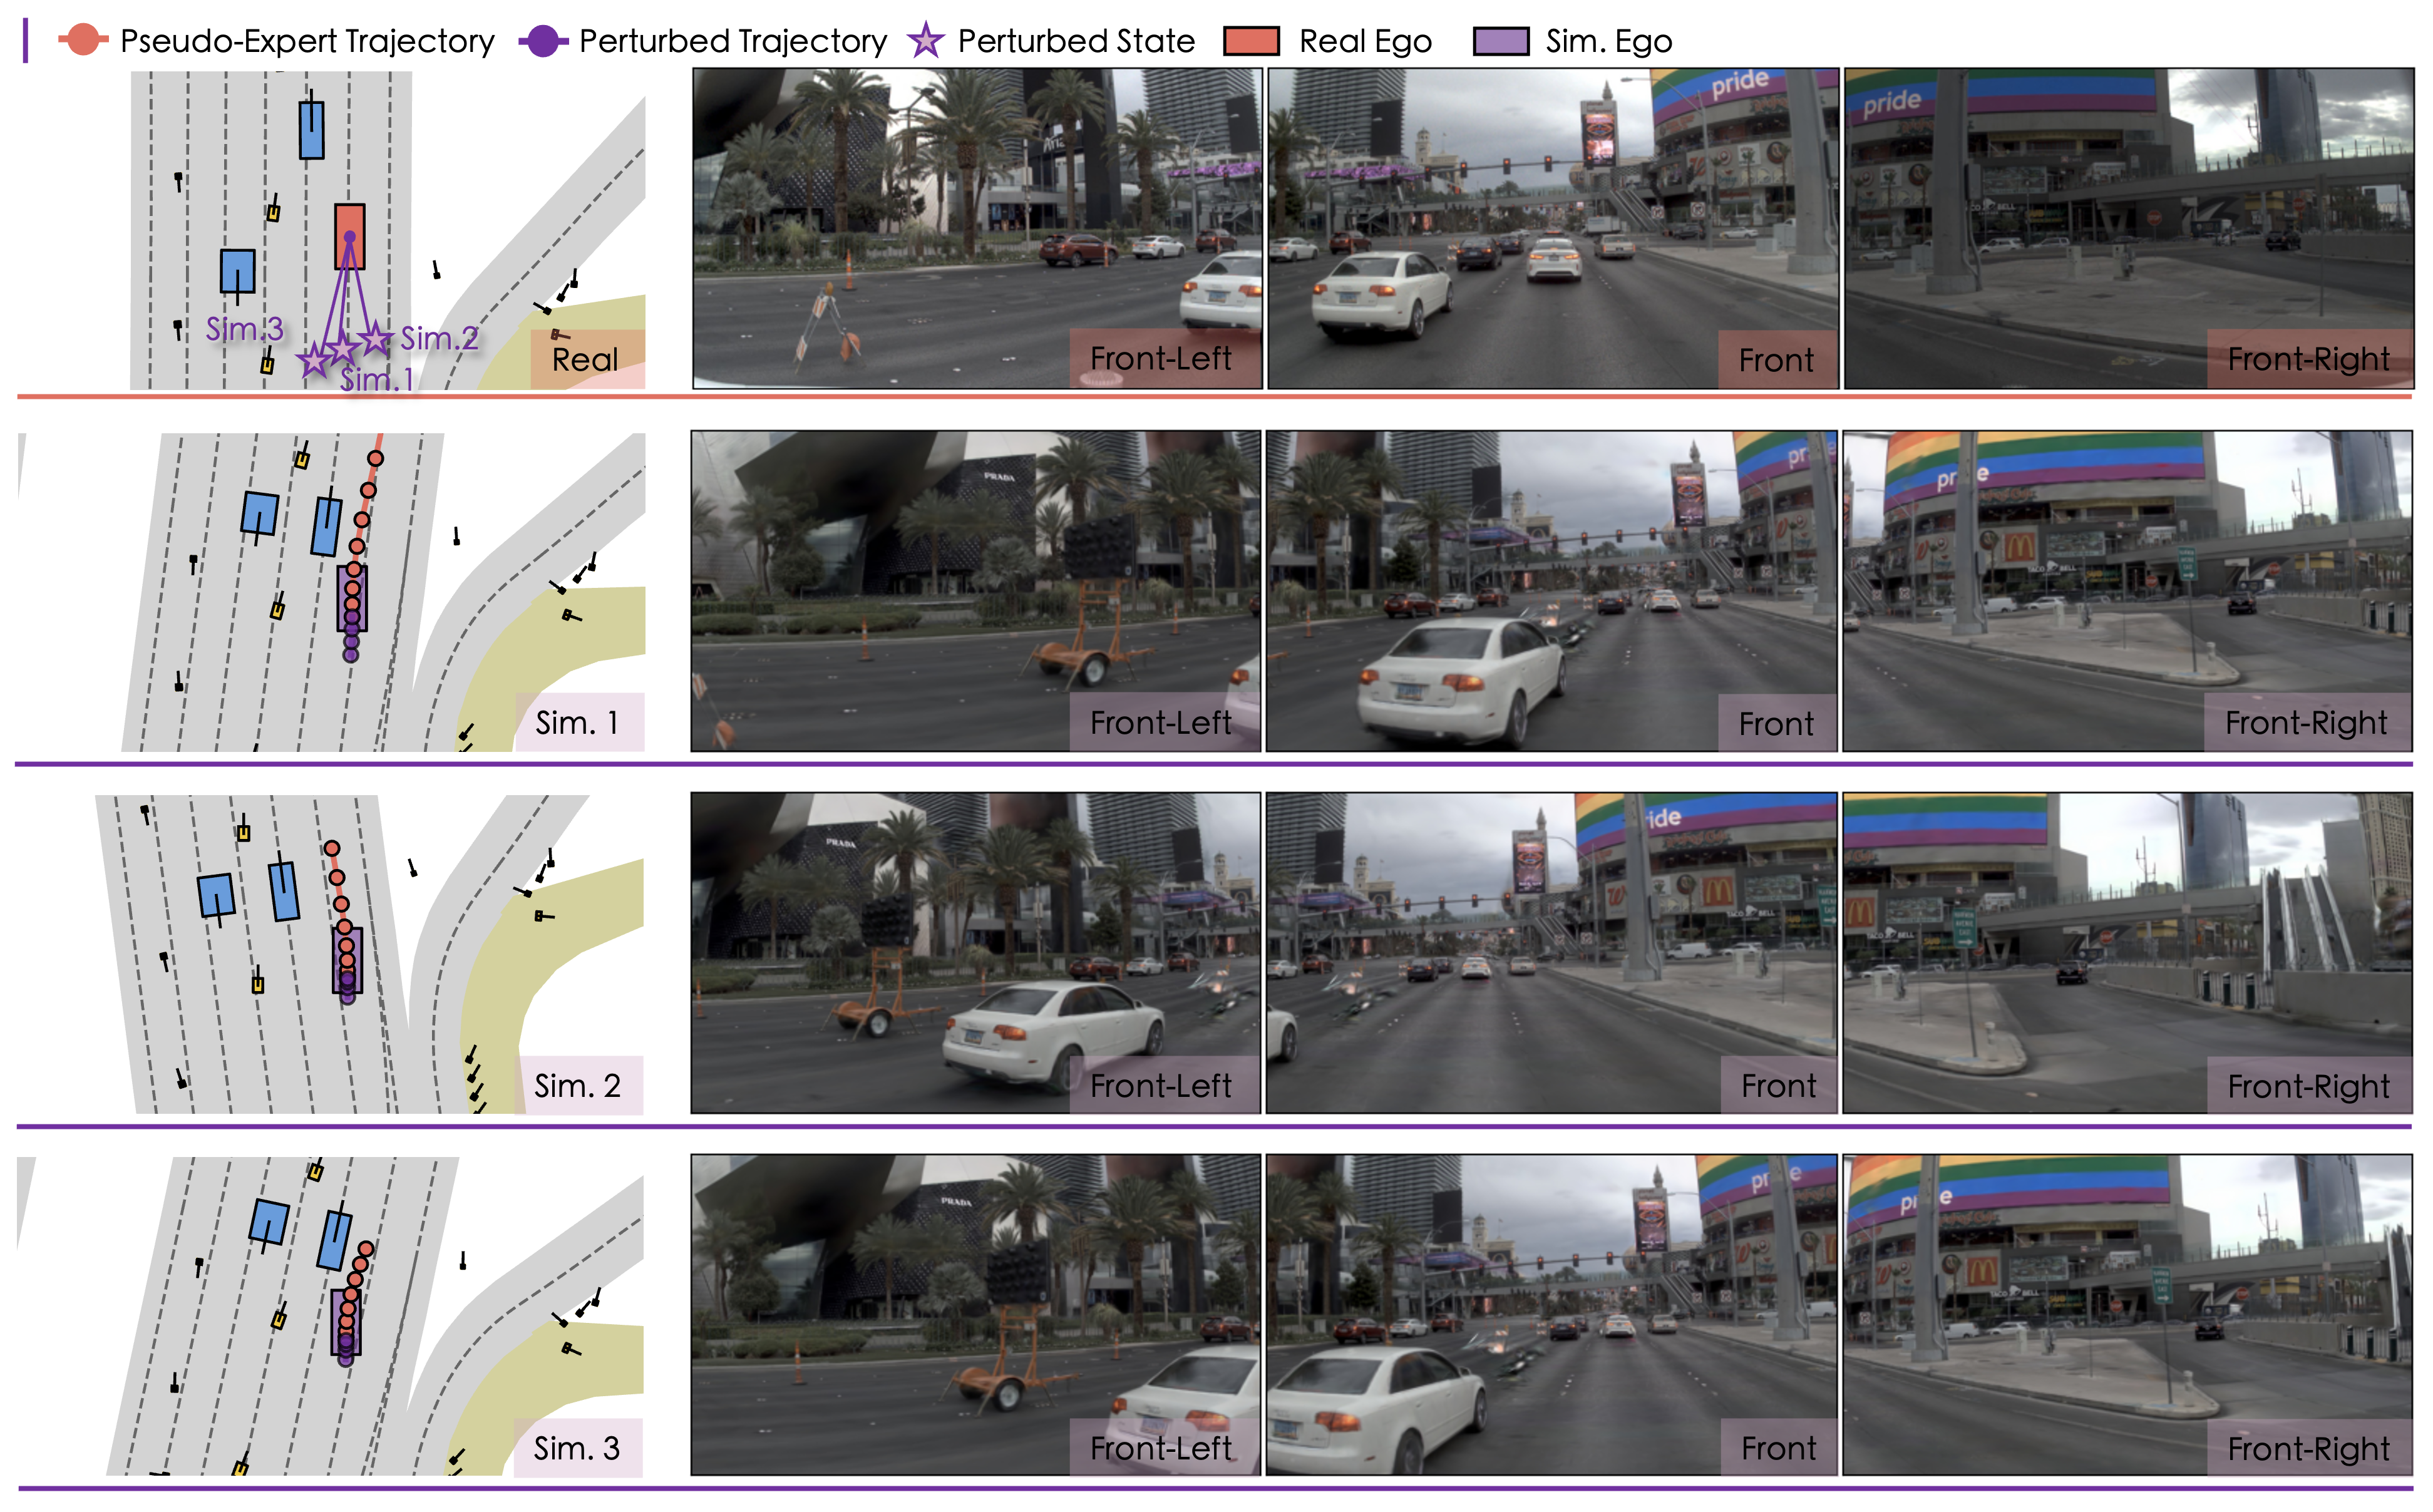
|
d37c49db3dcd59fa 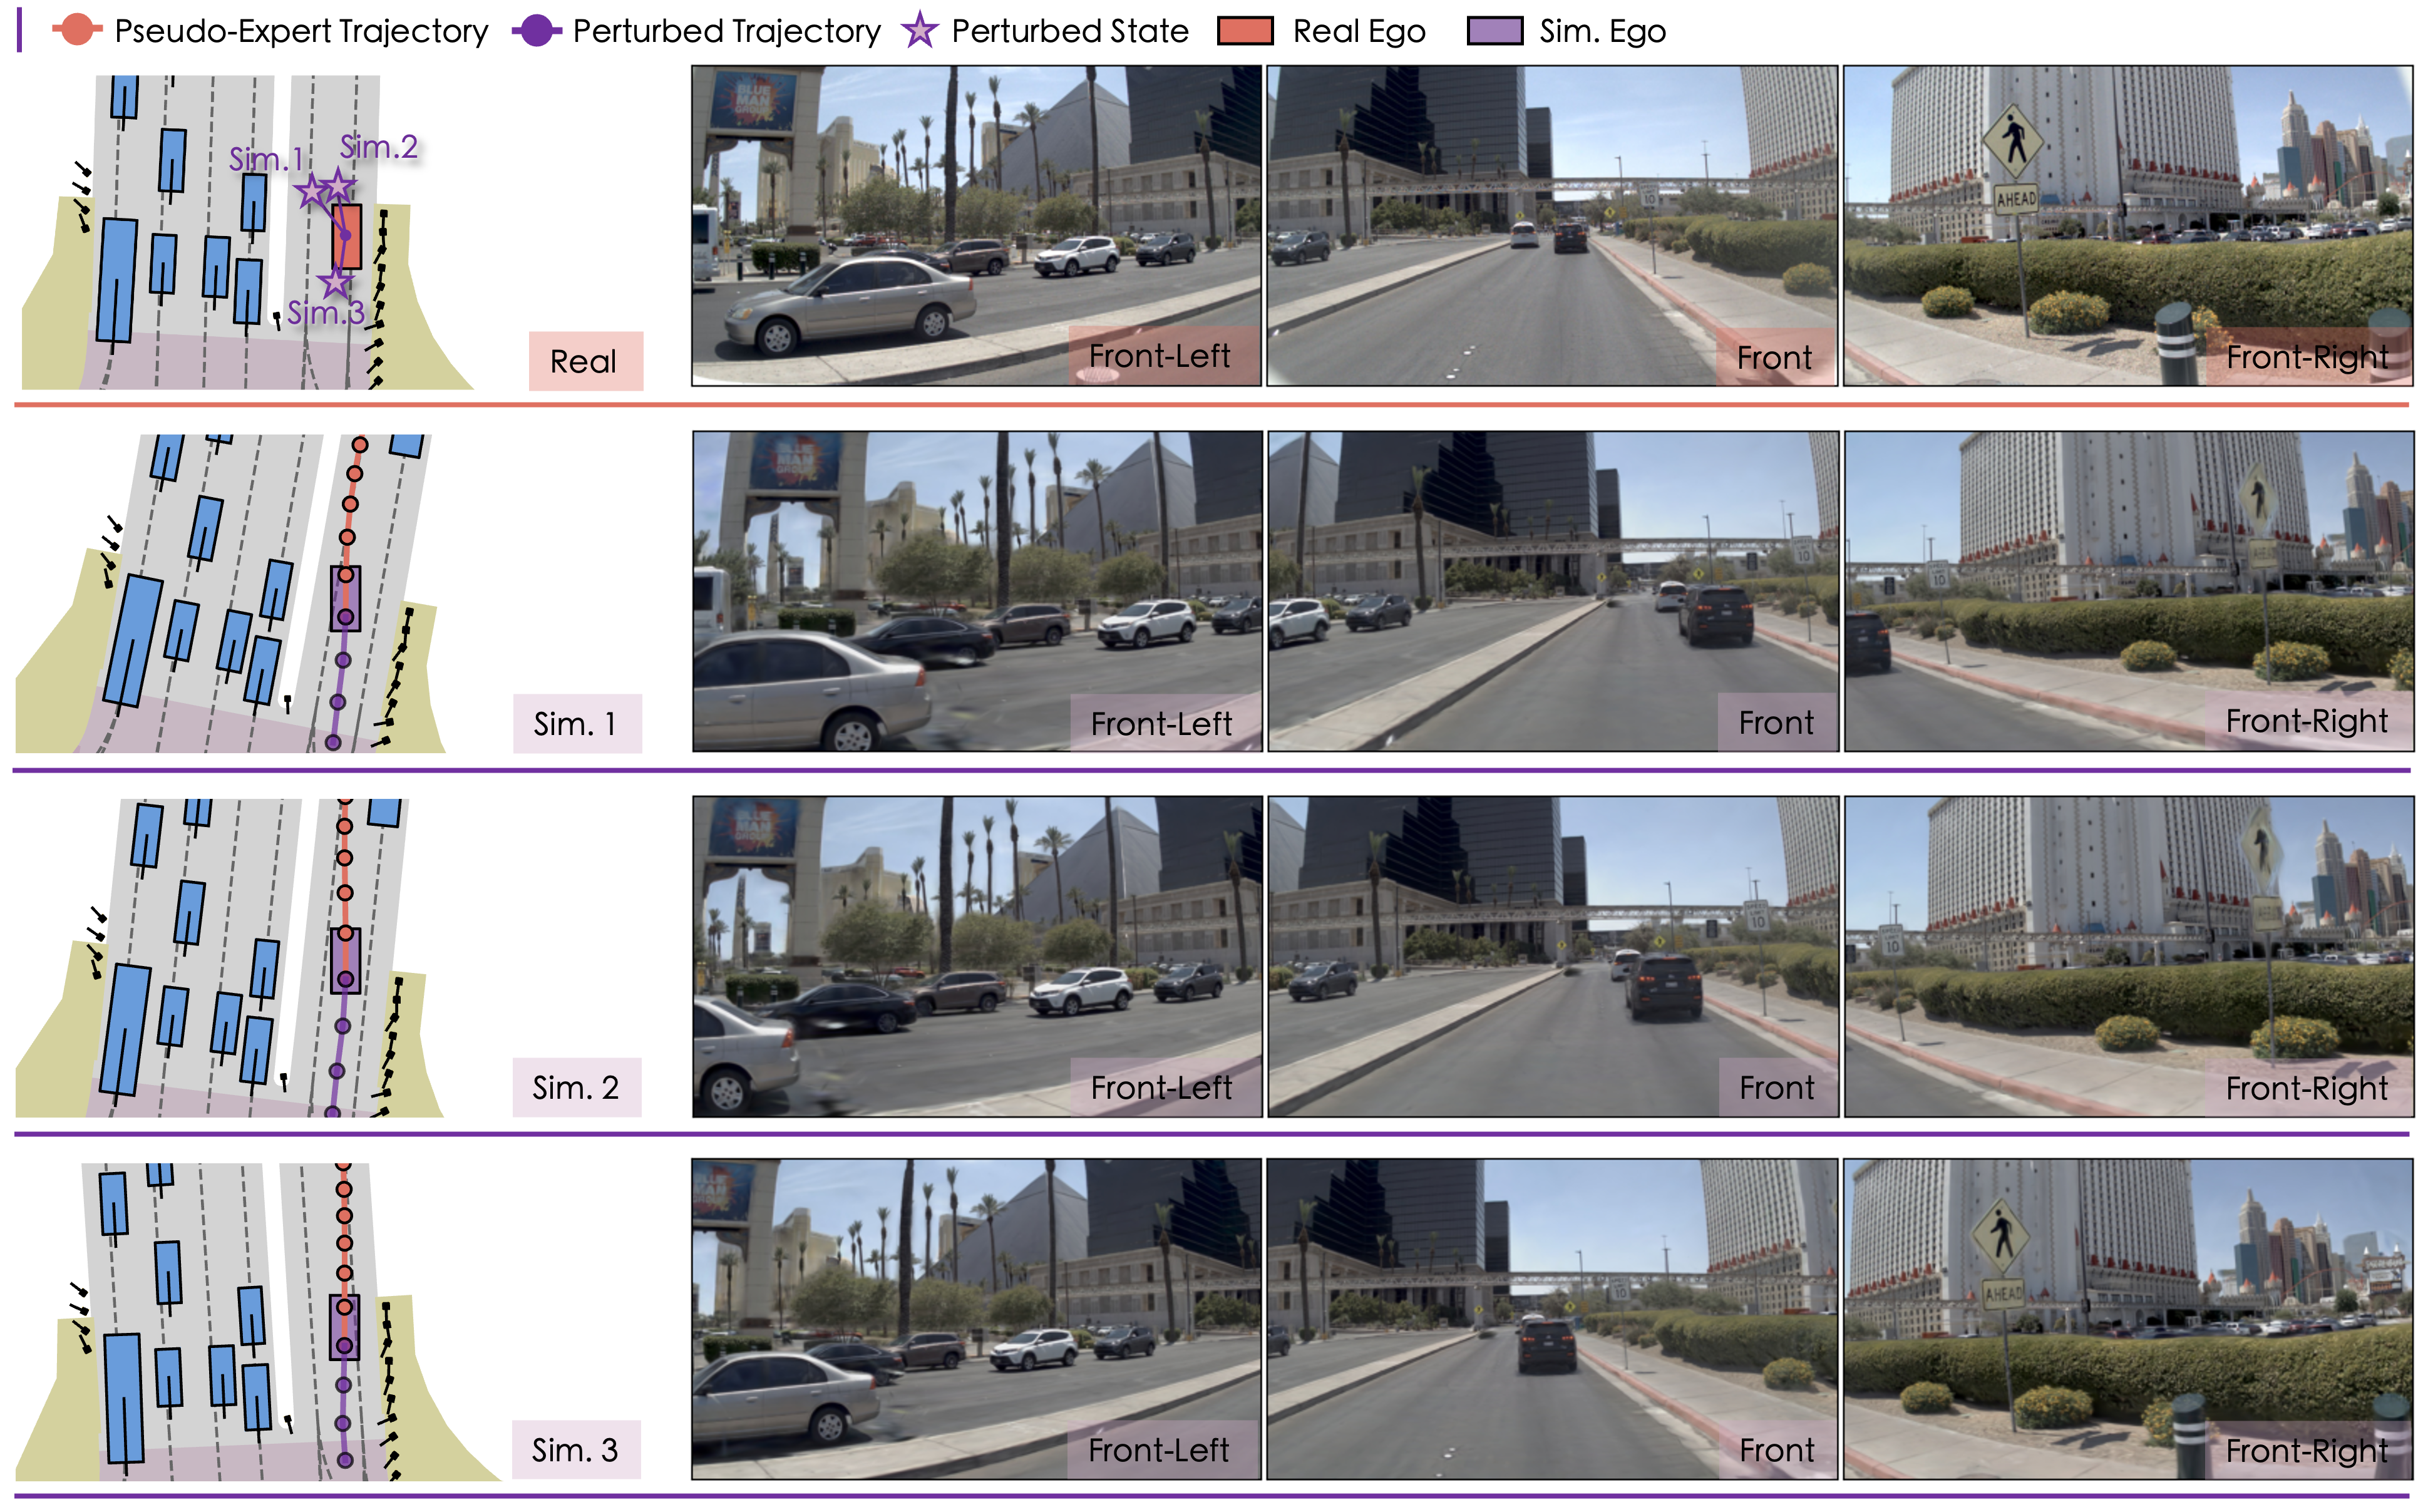
|
|
Sim. 1 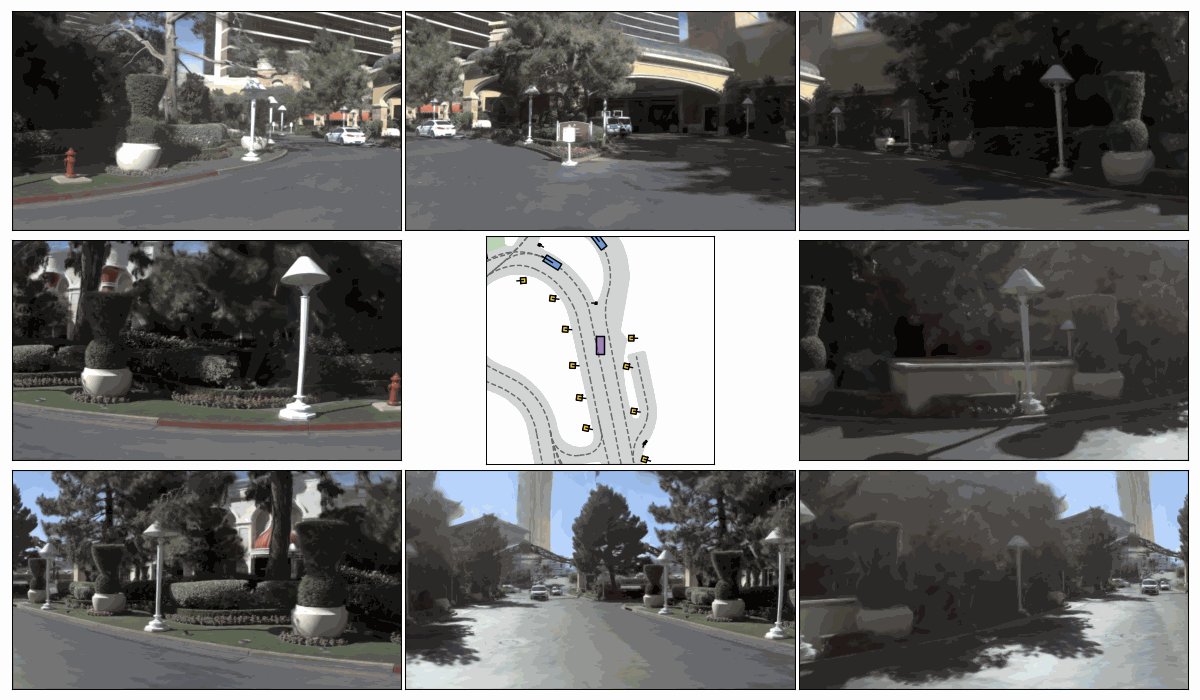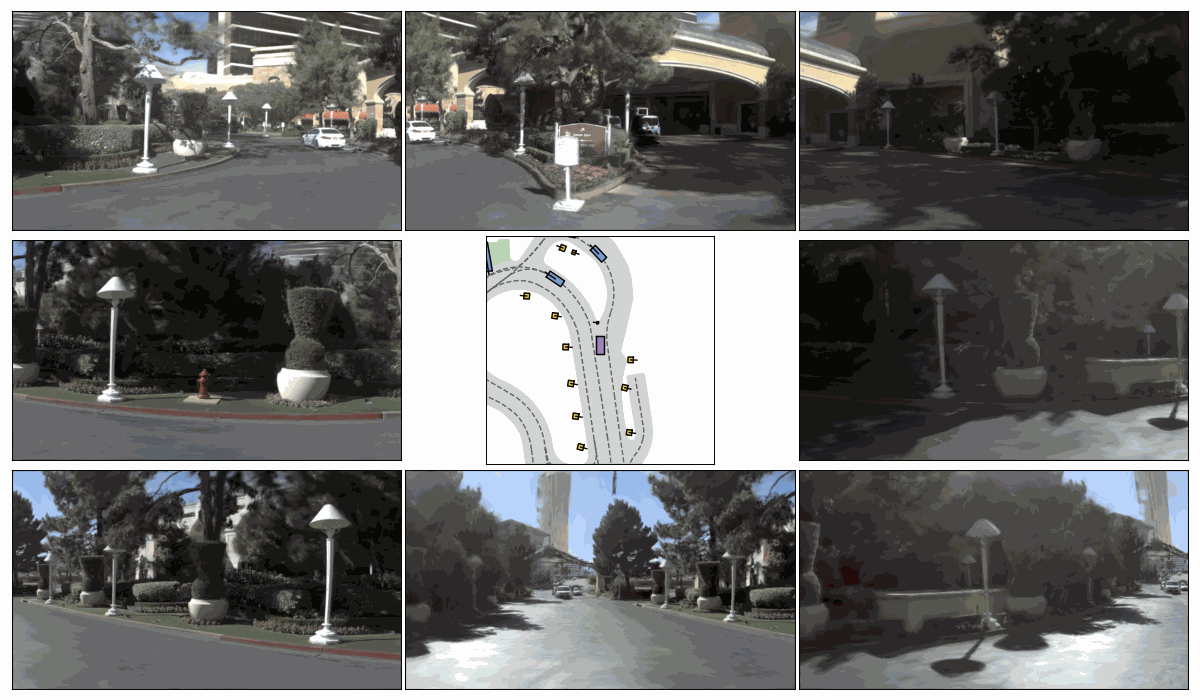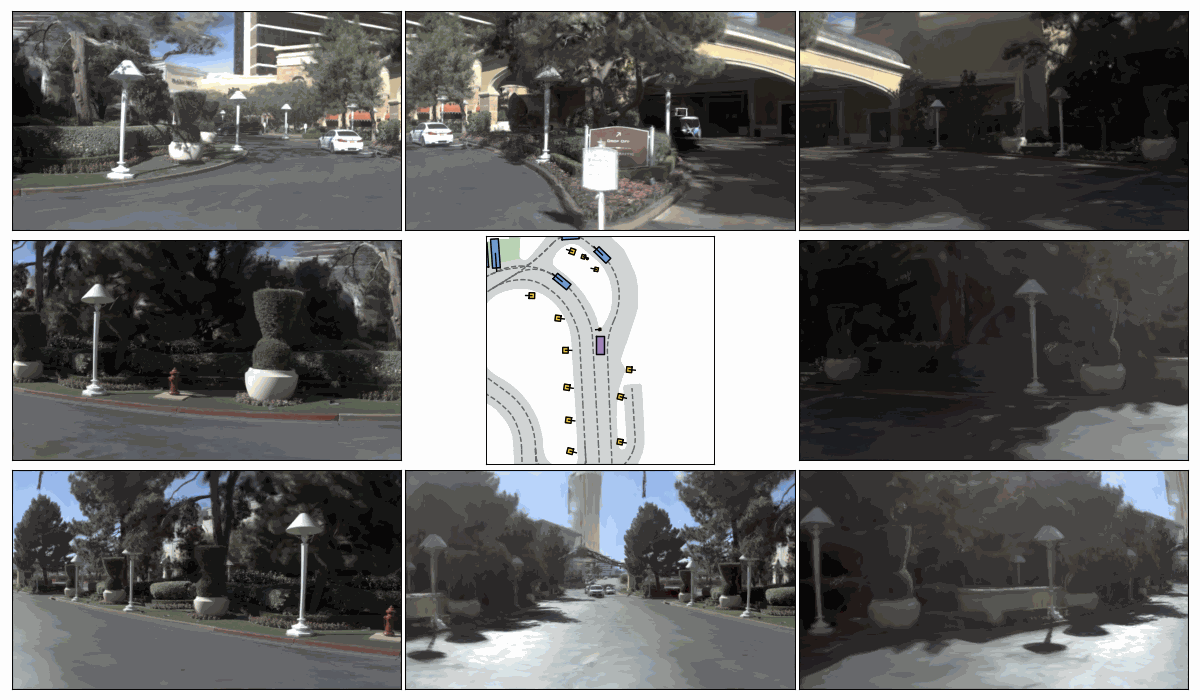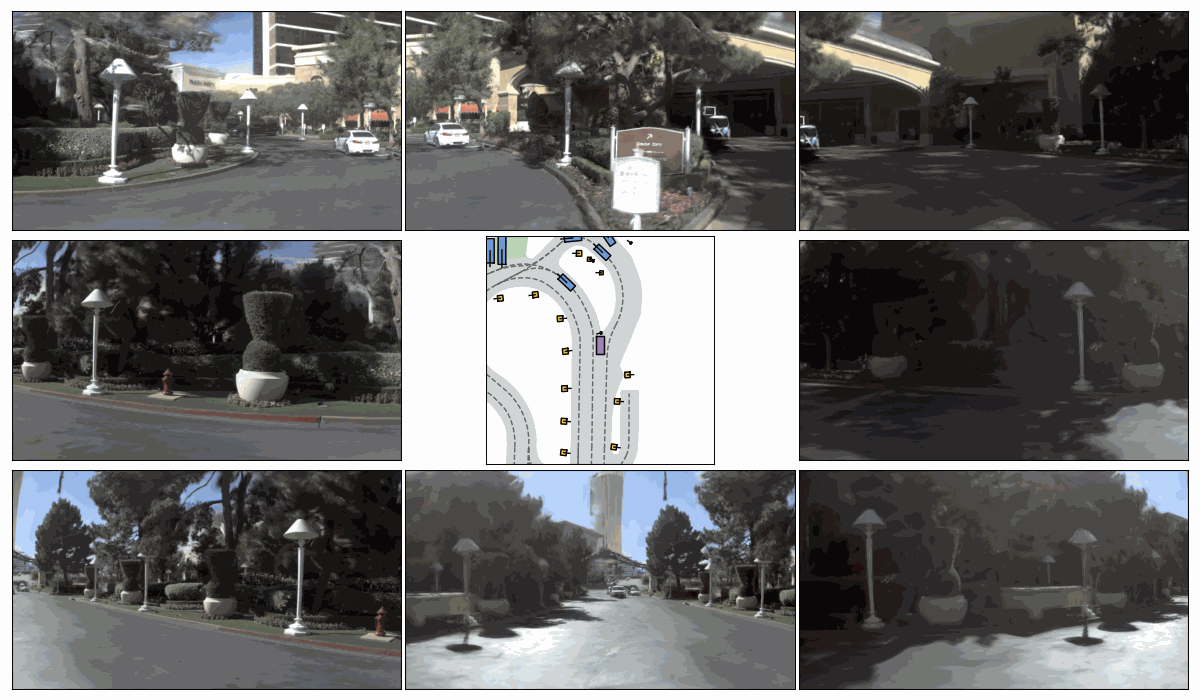 Sim. 2 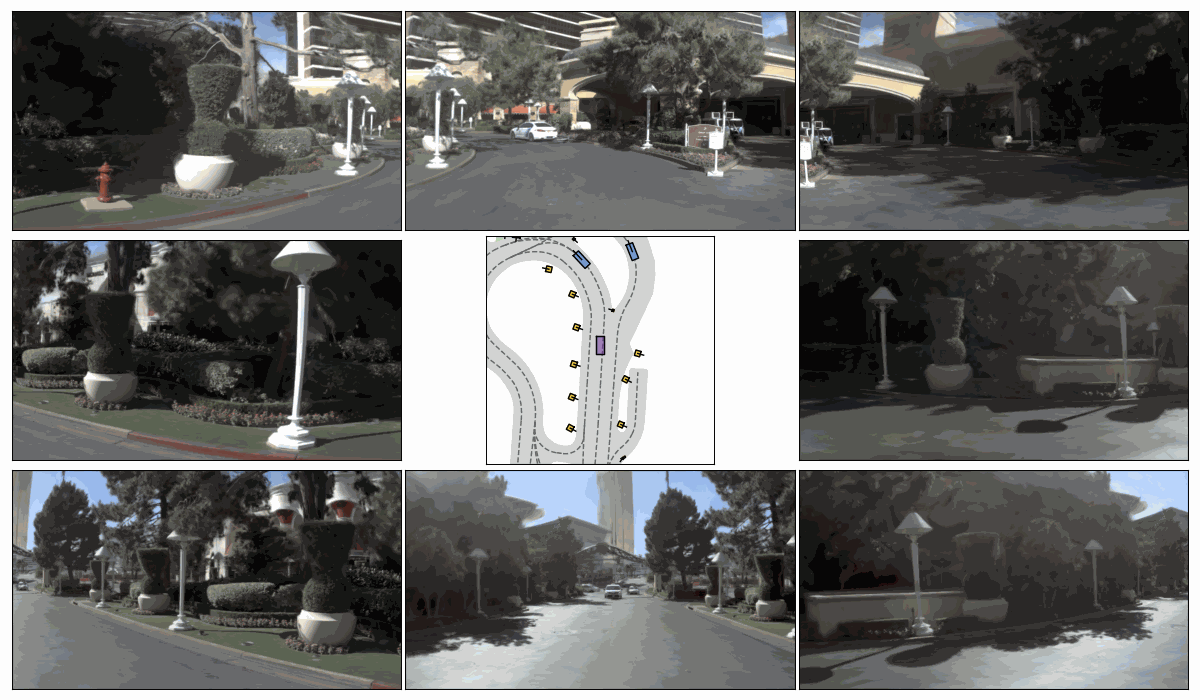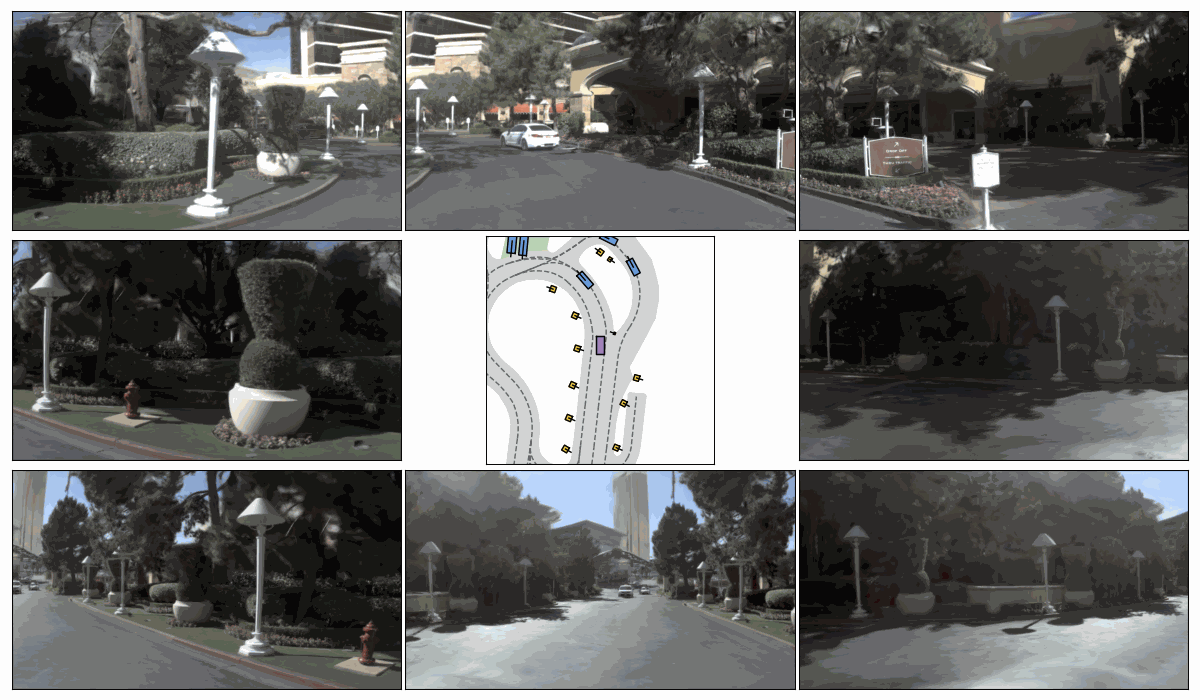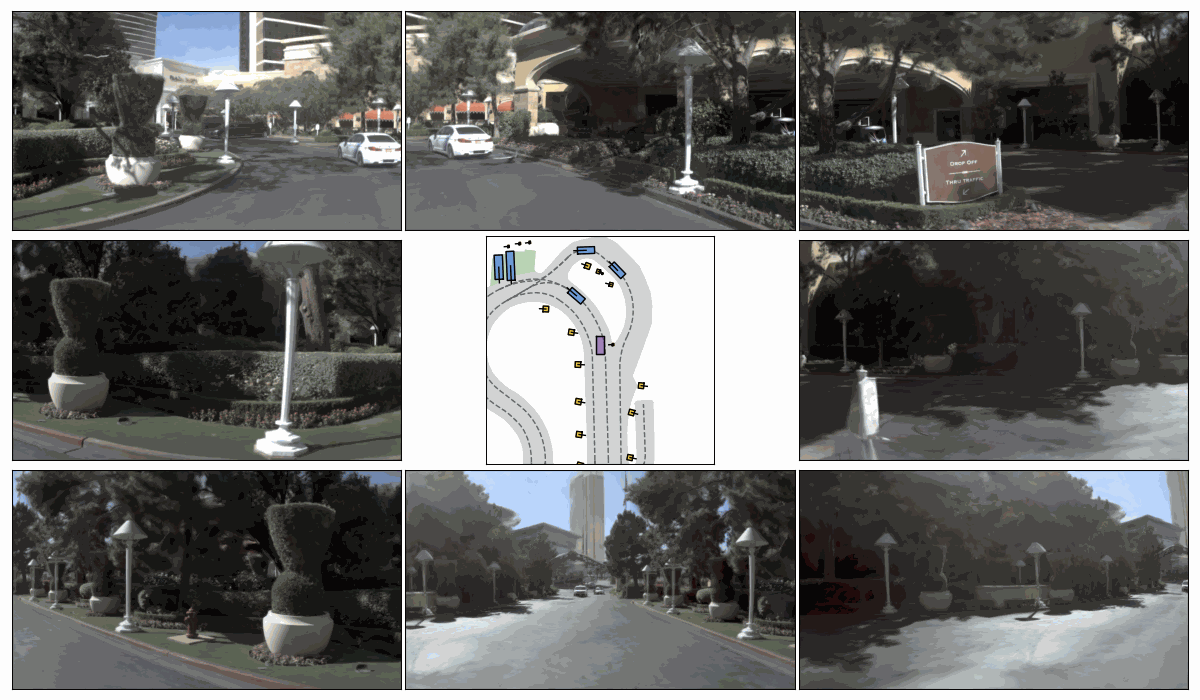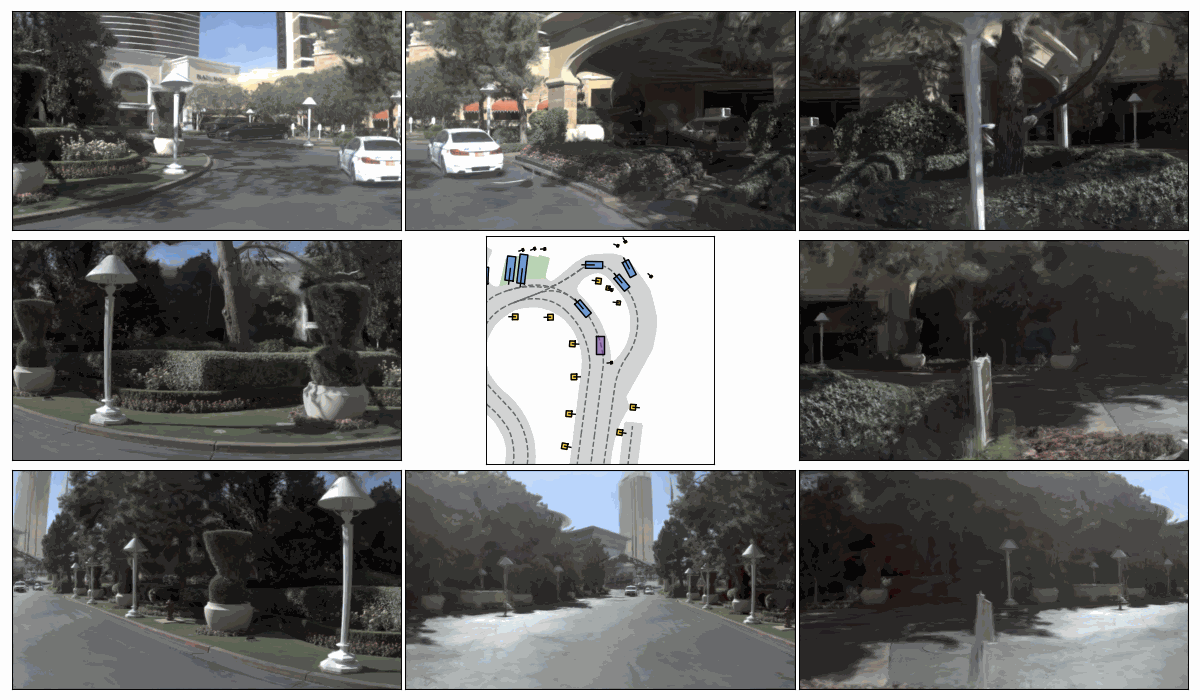 Sim. 3 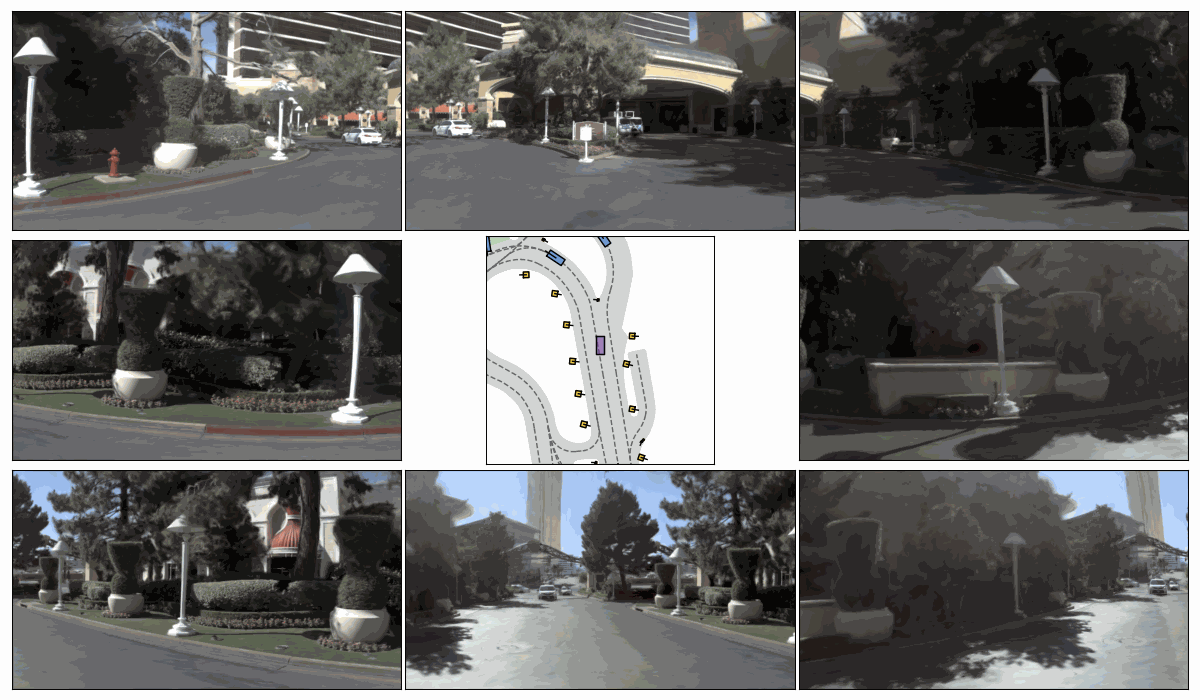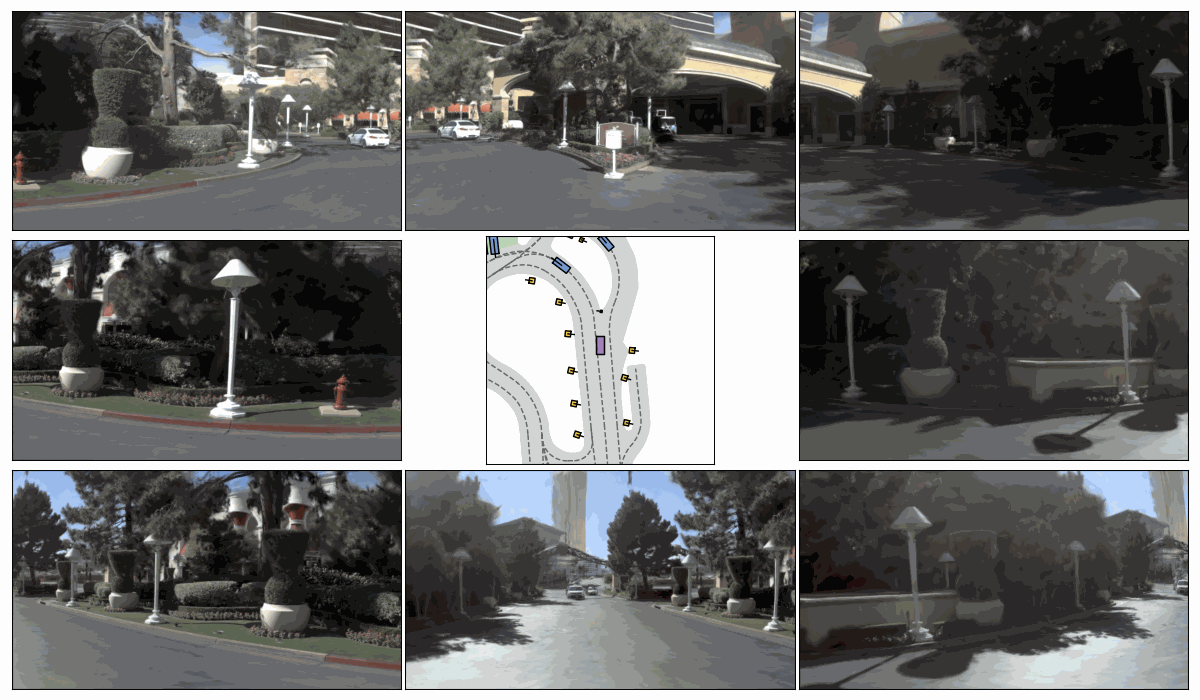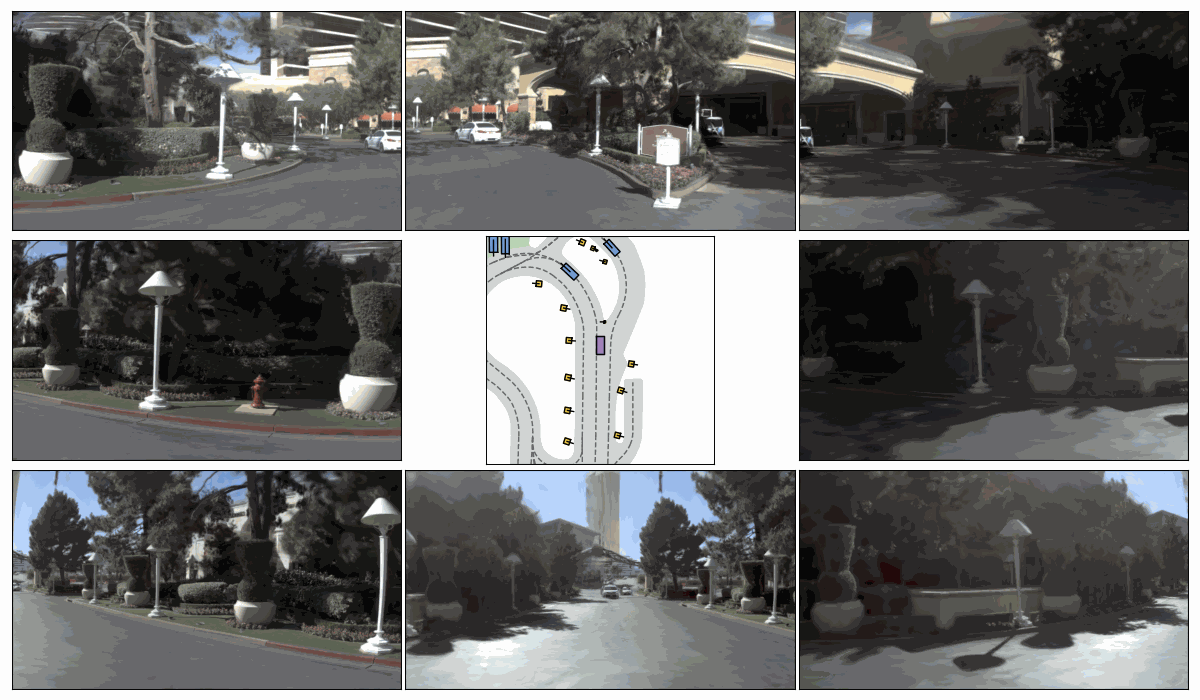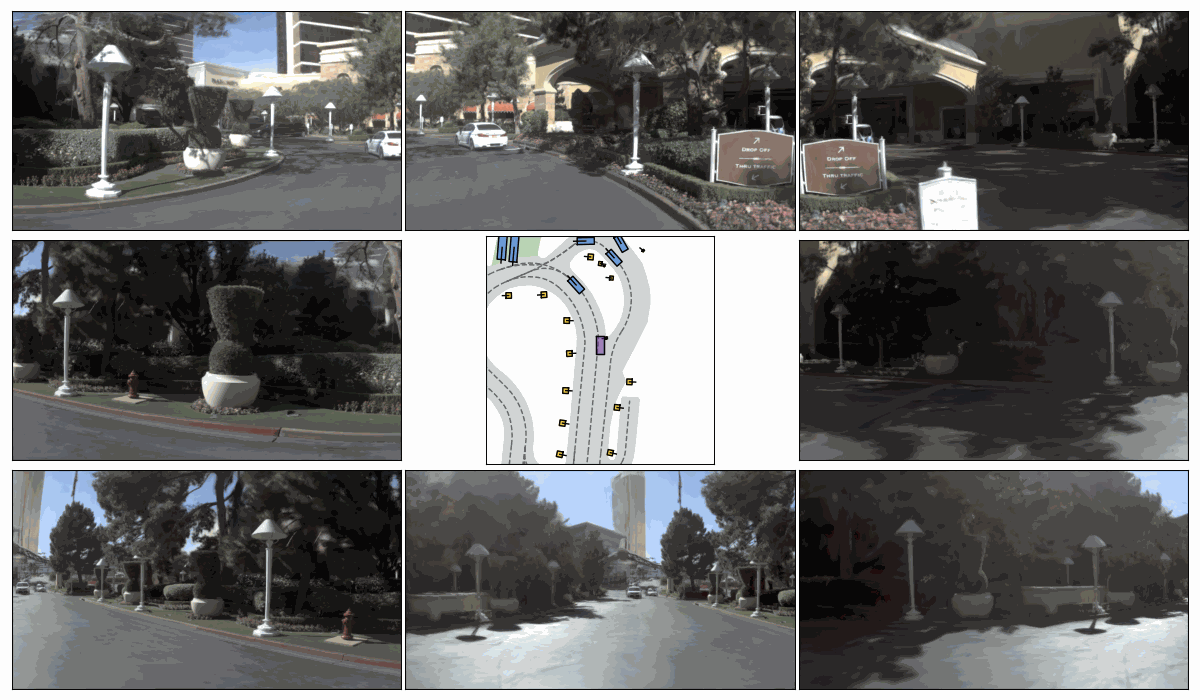
|
Sim. 1 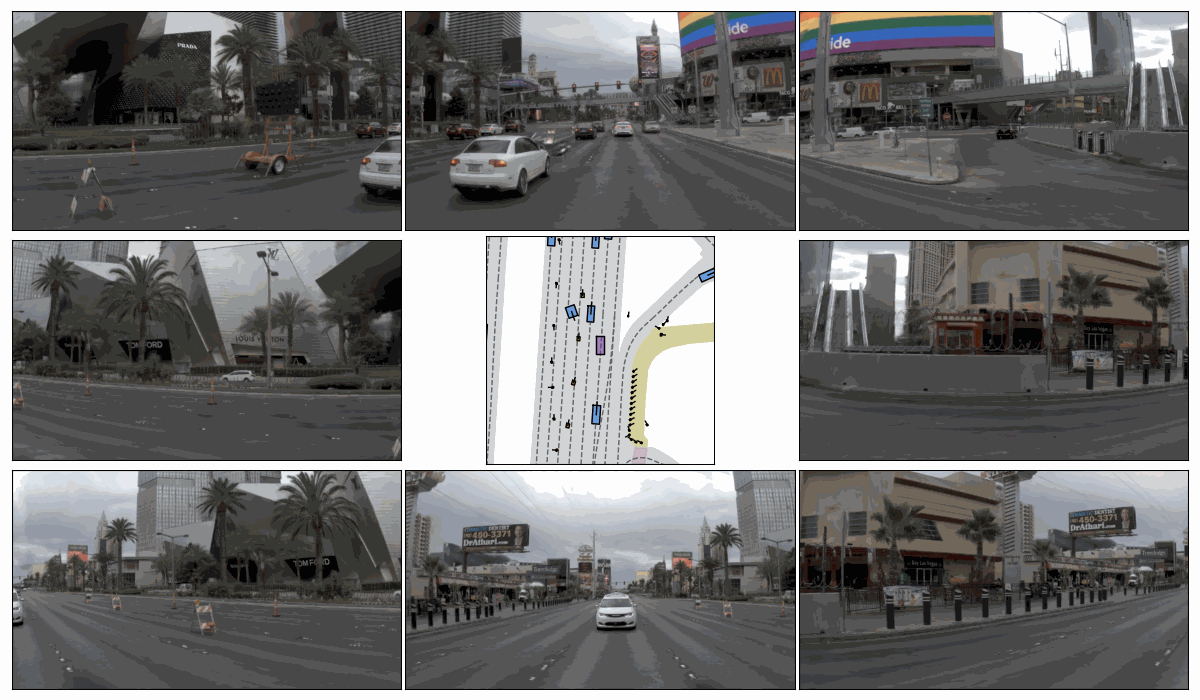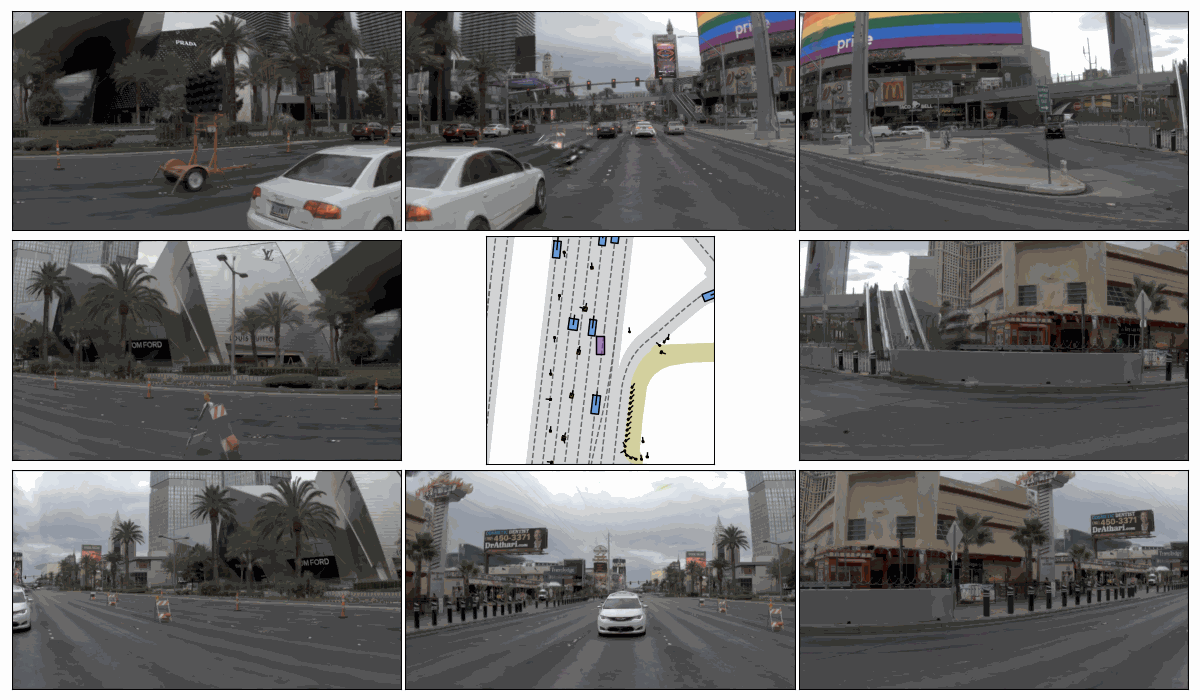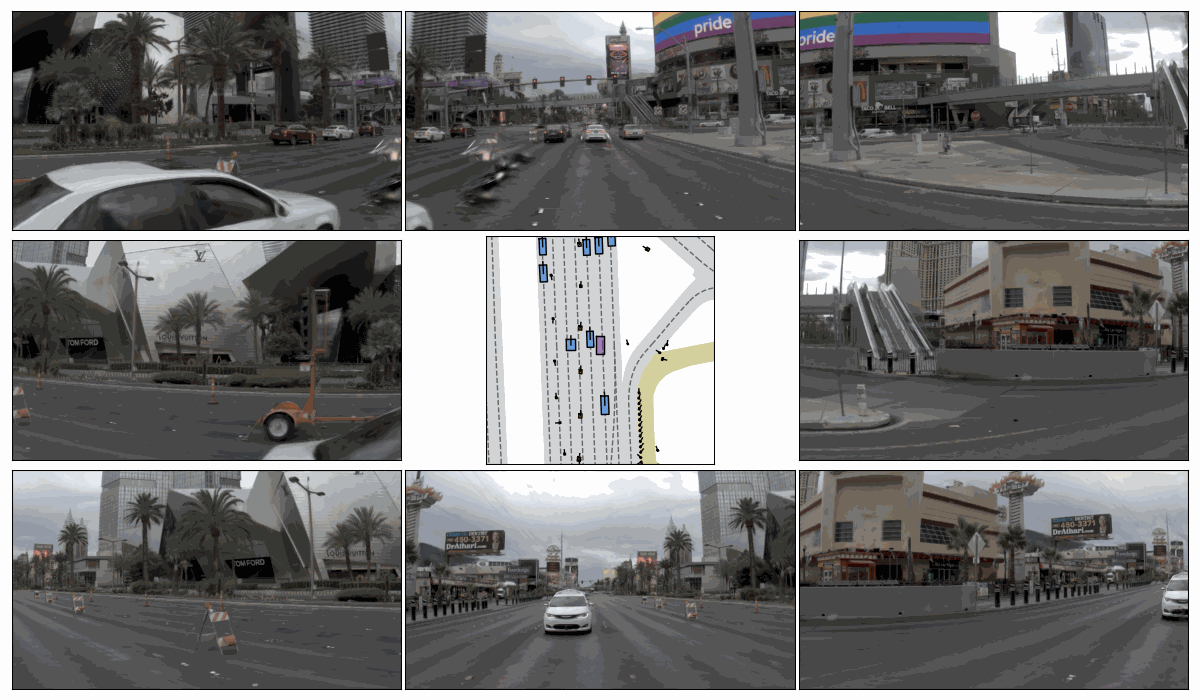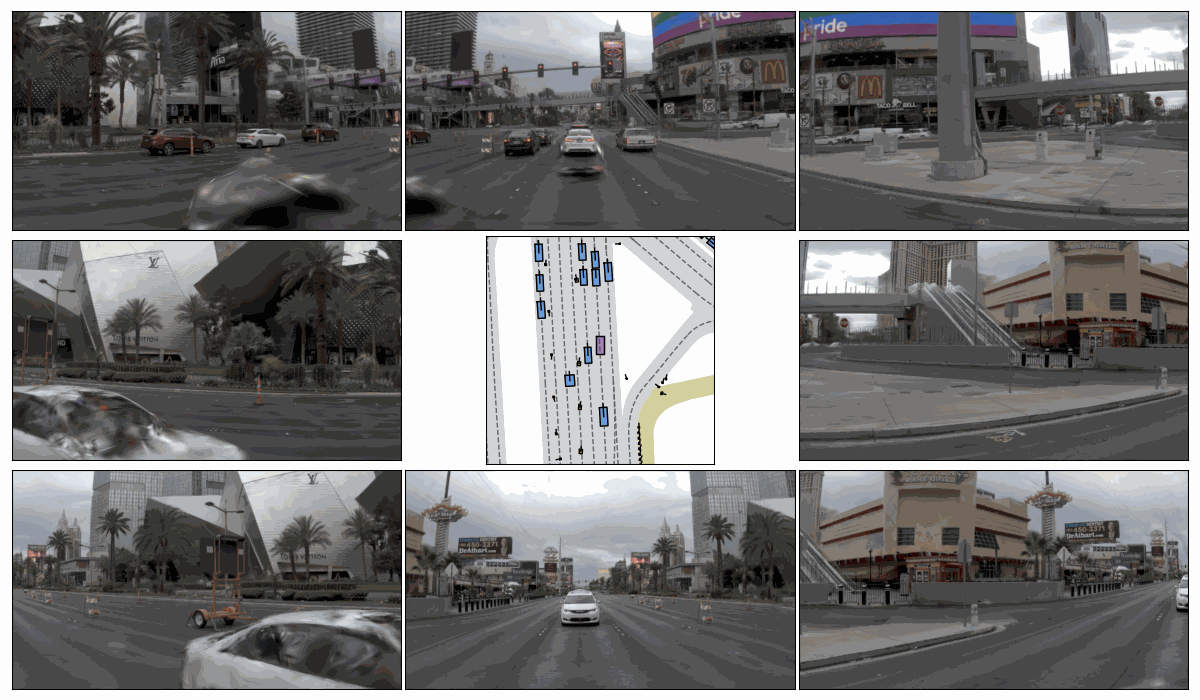 Sim. 2 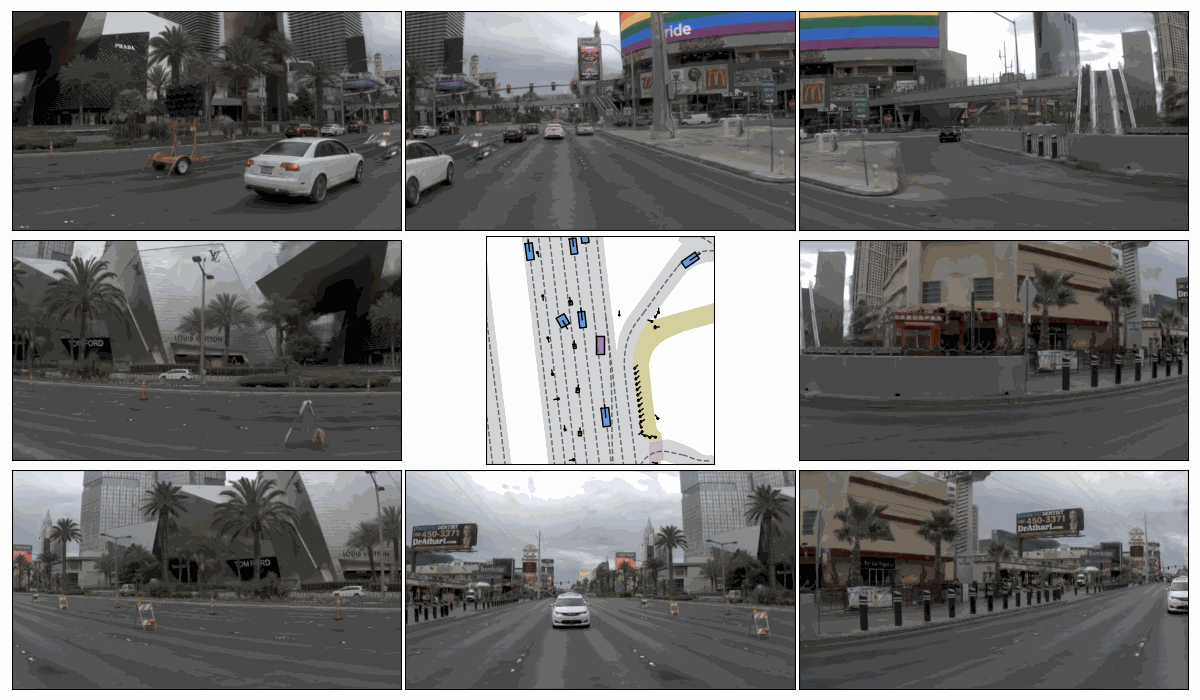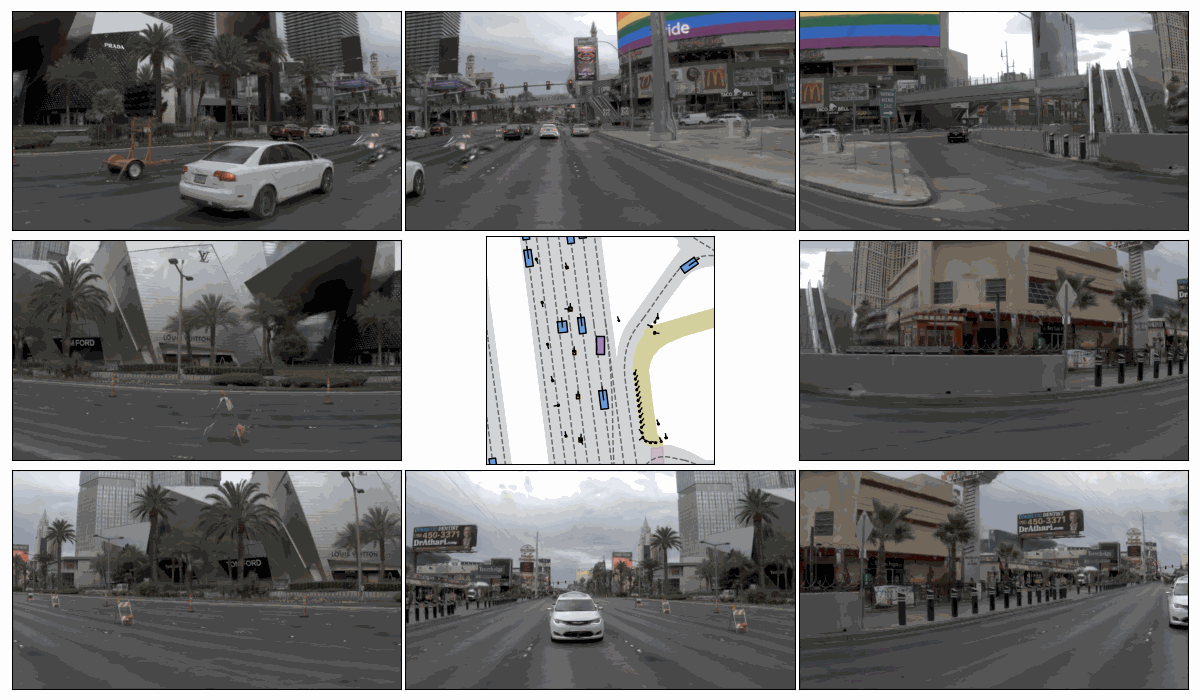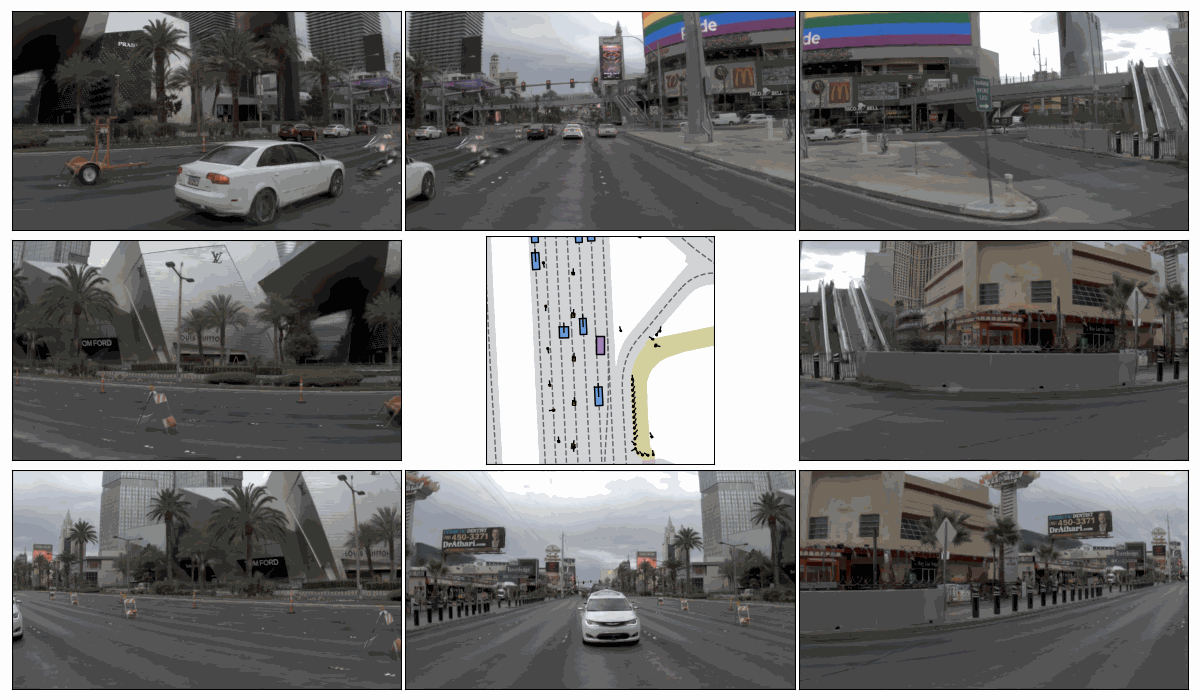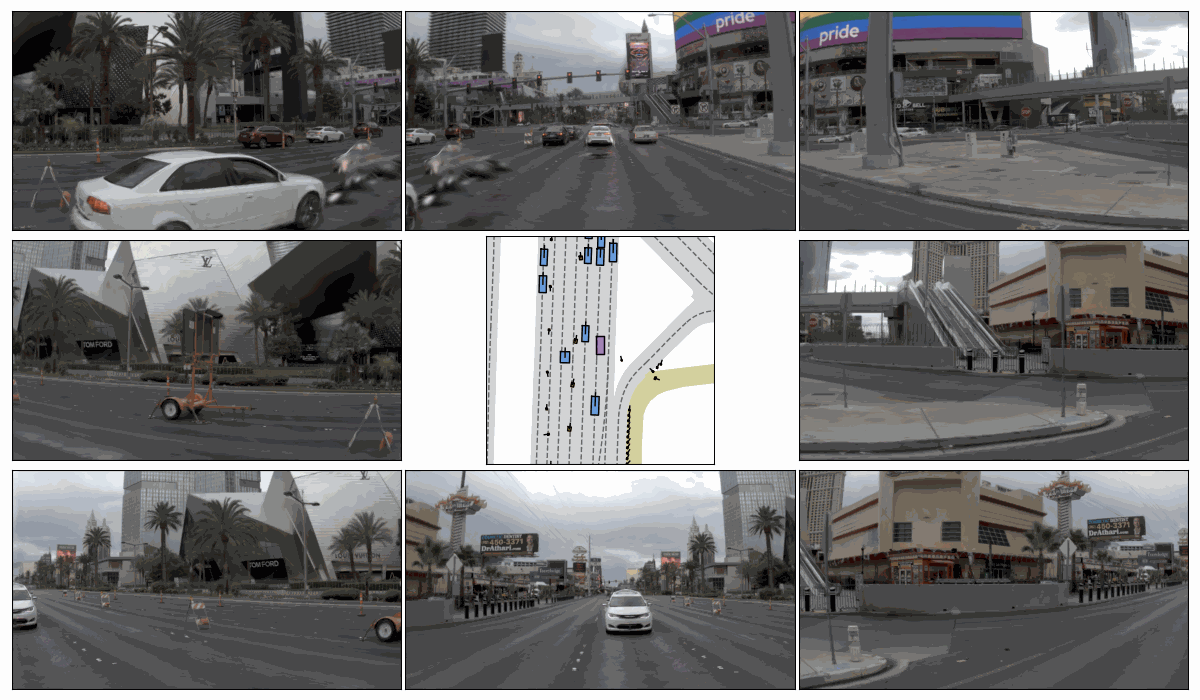 Sim. 3 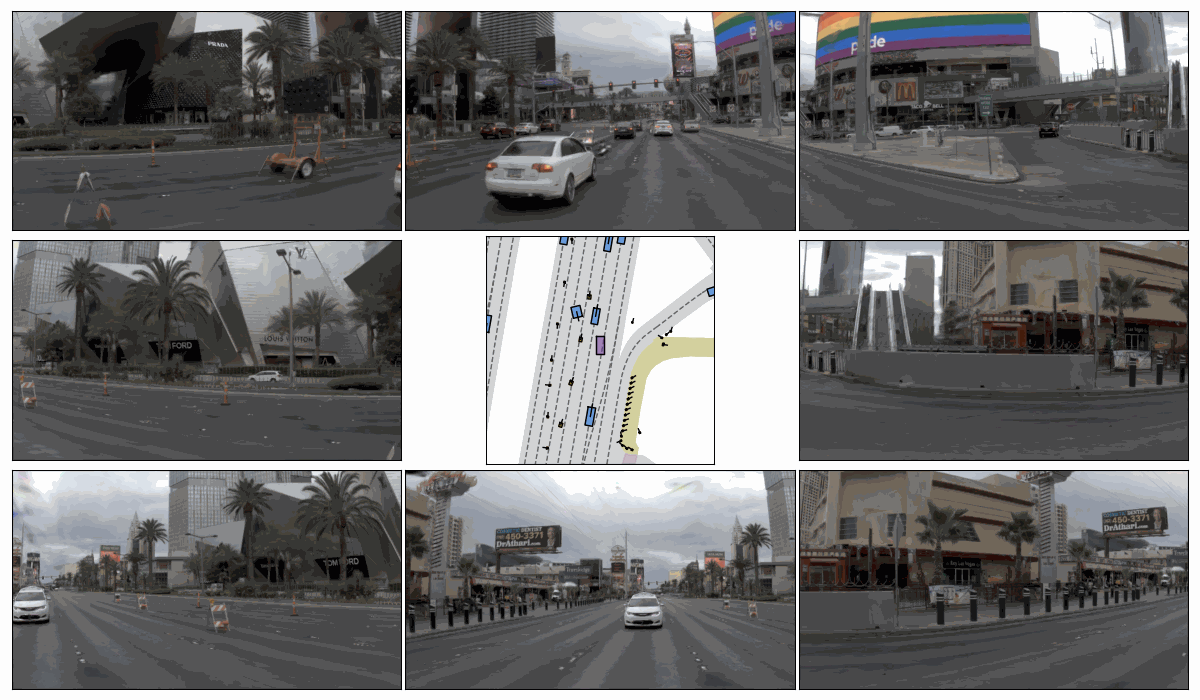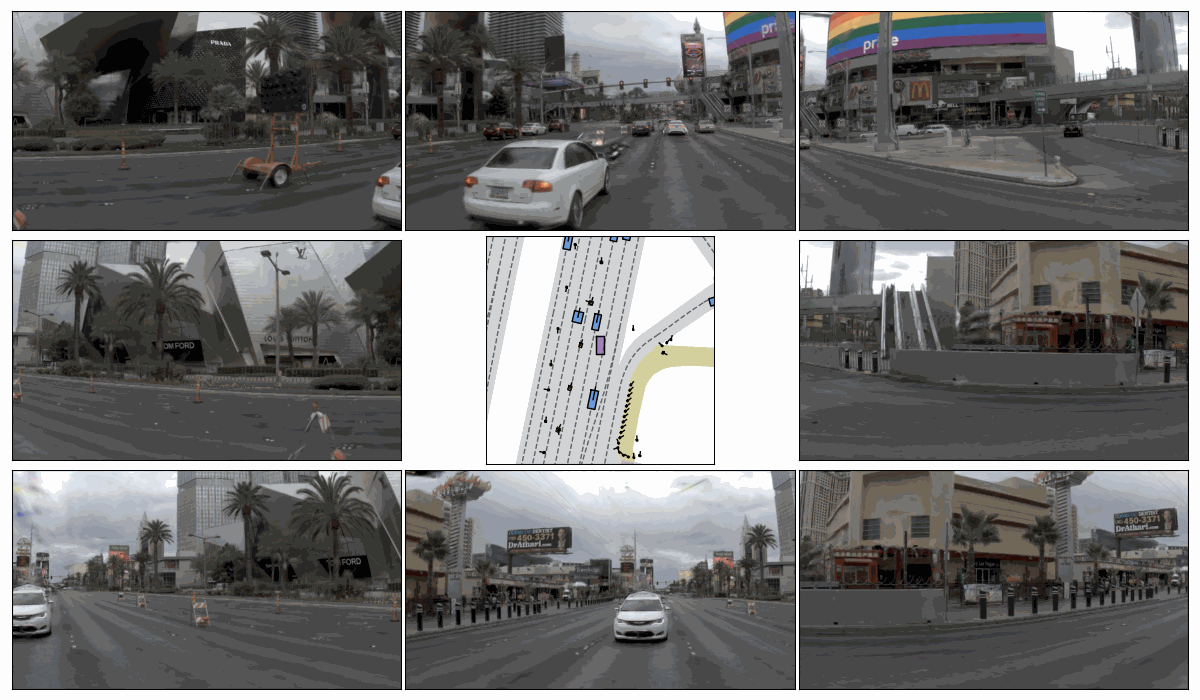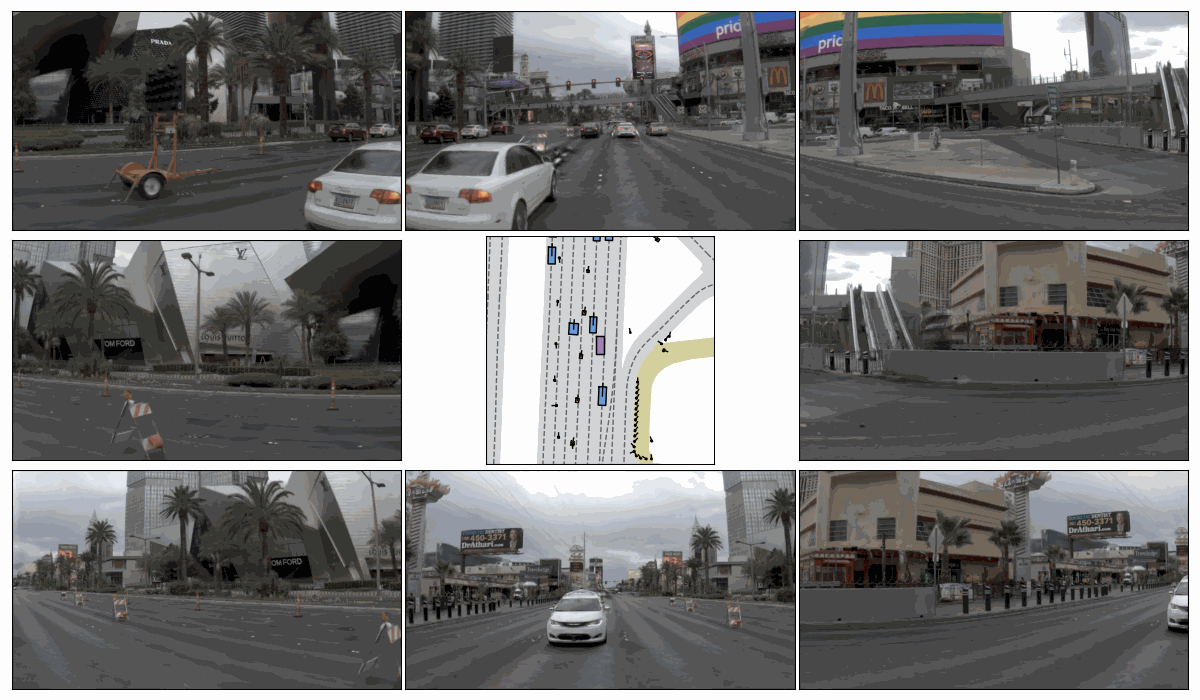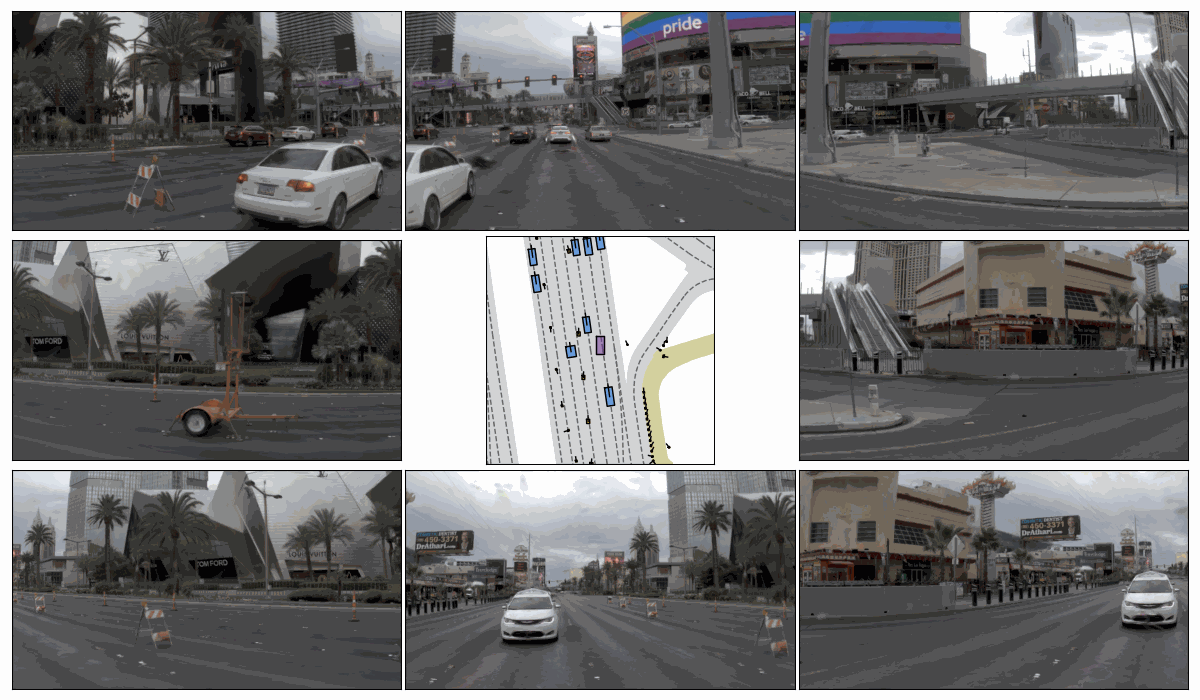
|
Sim. 1 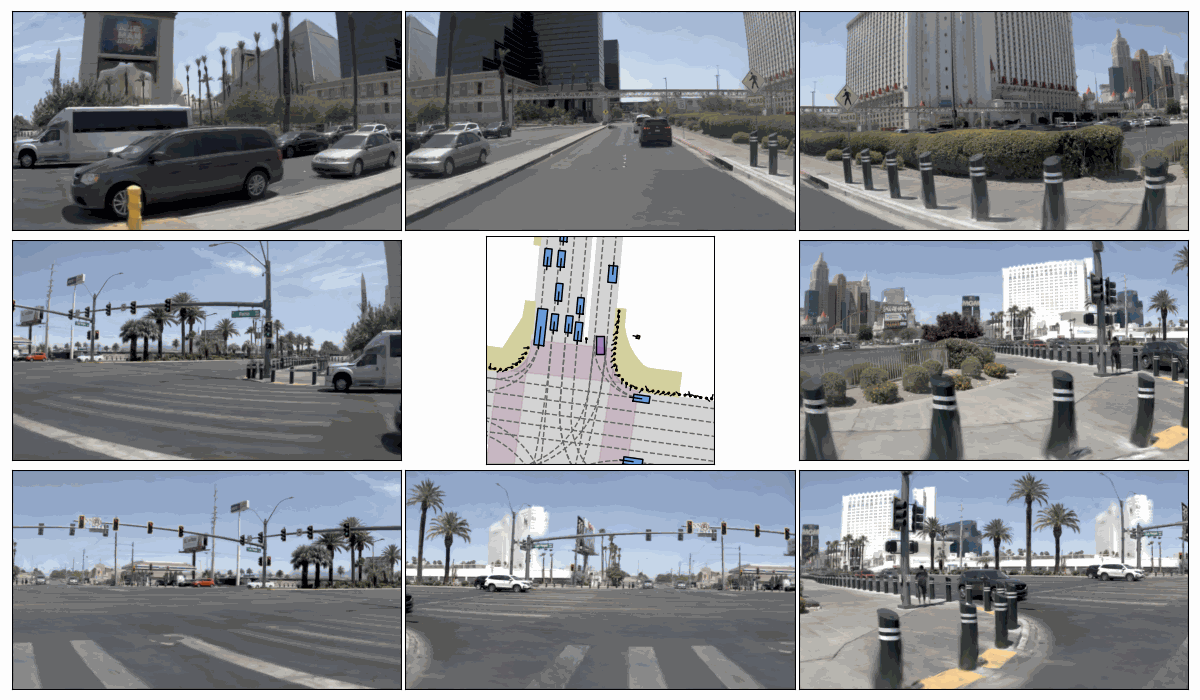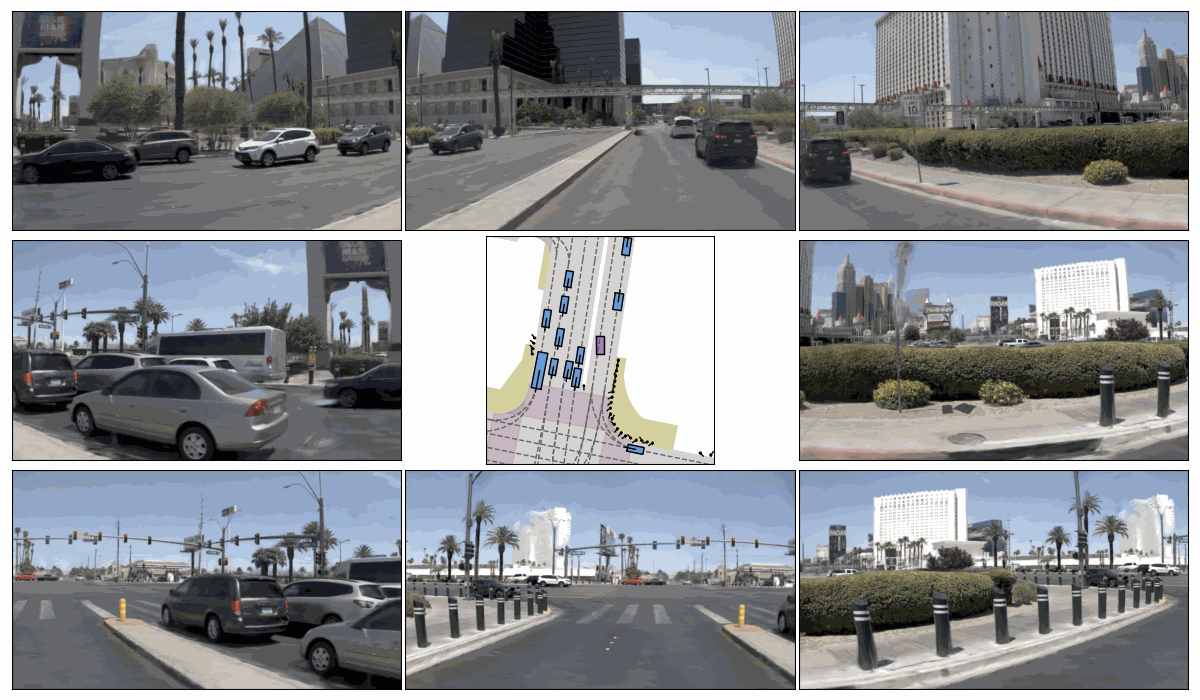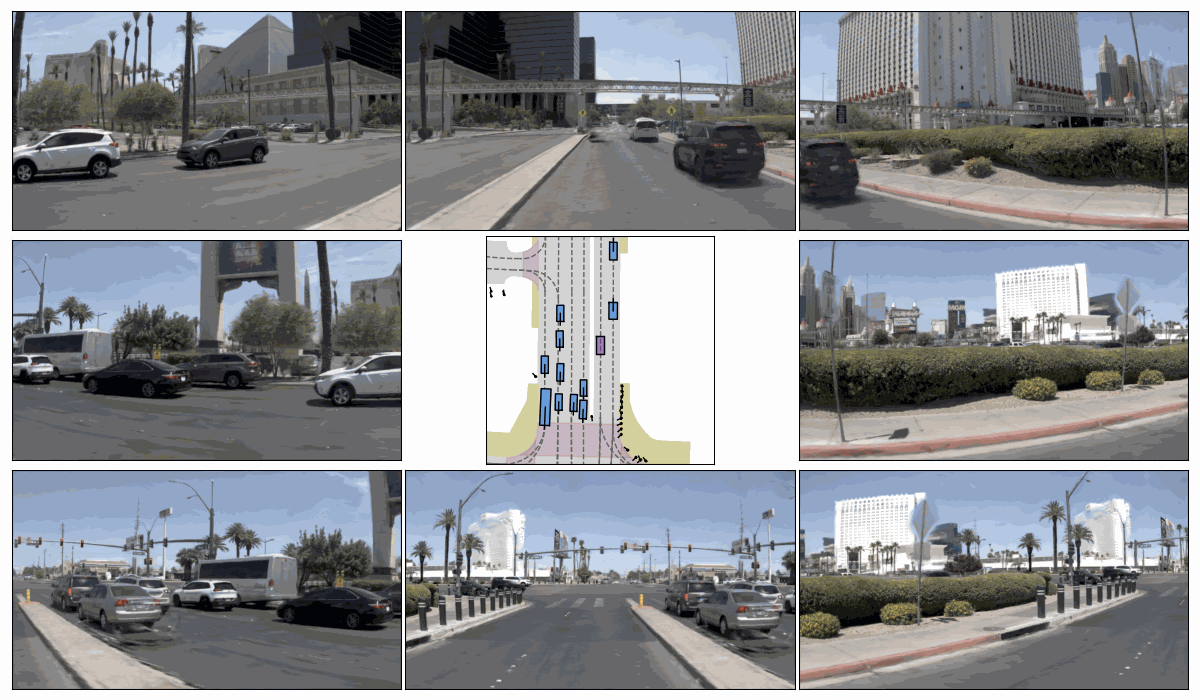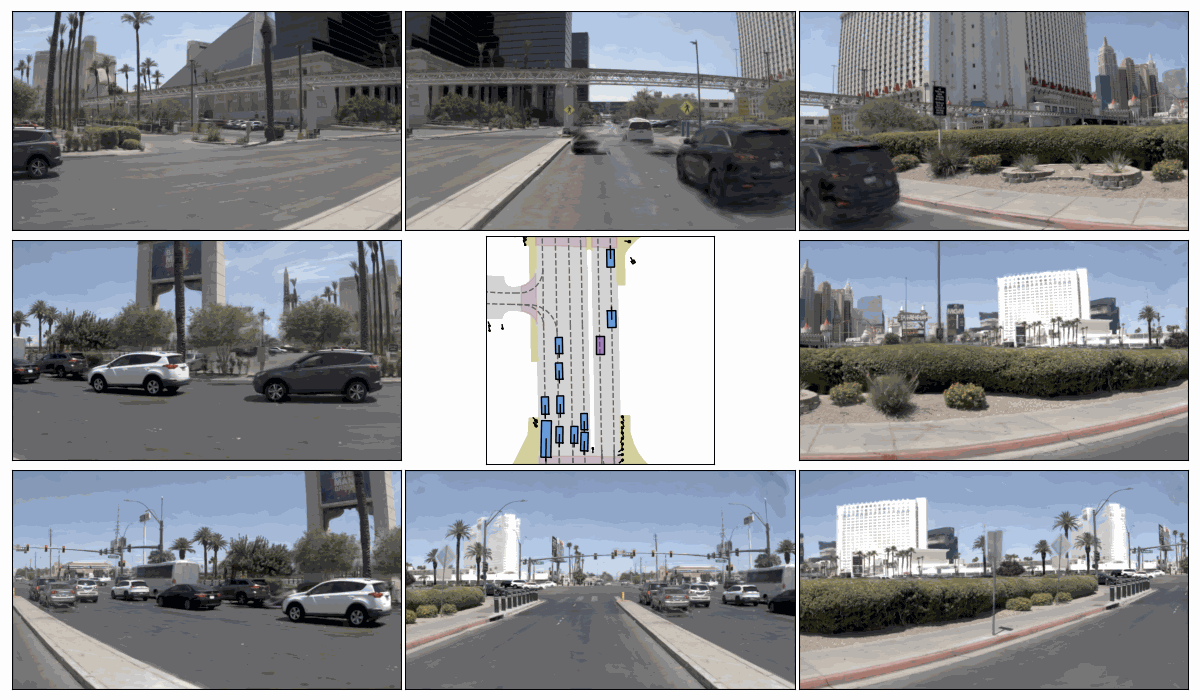 Sim. 2 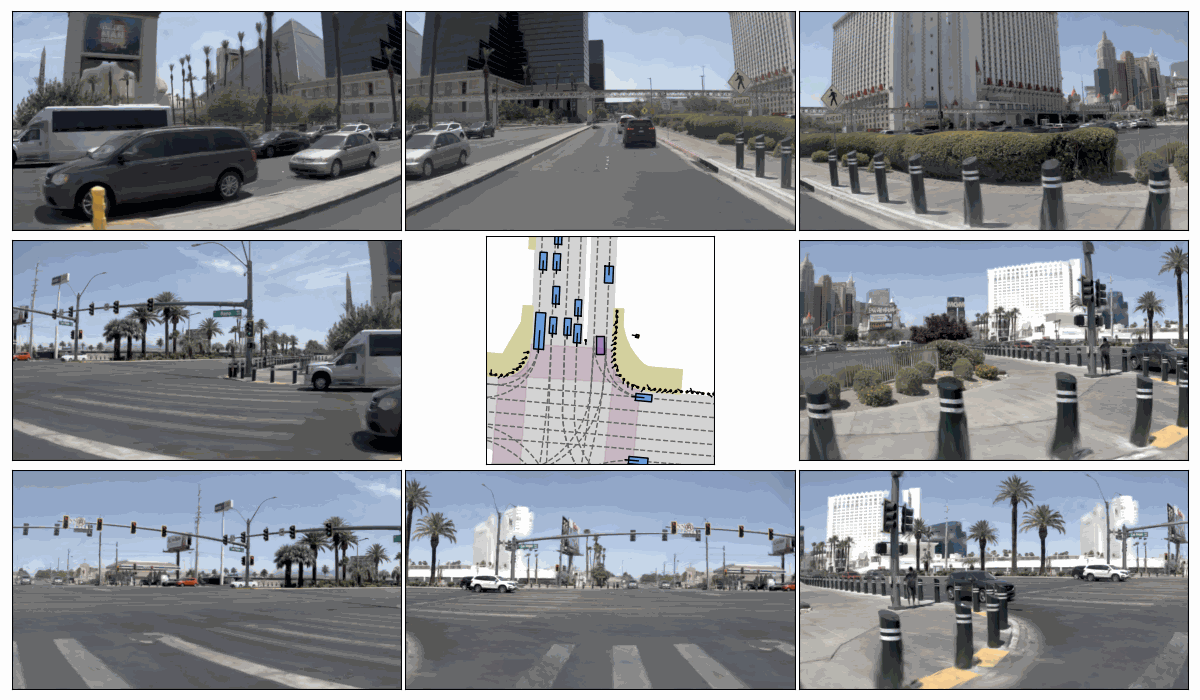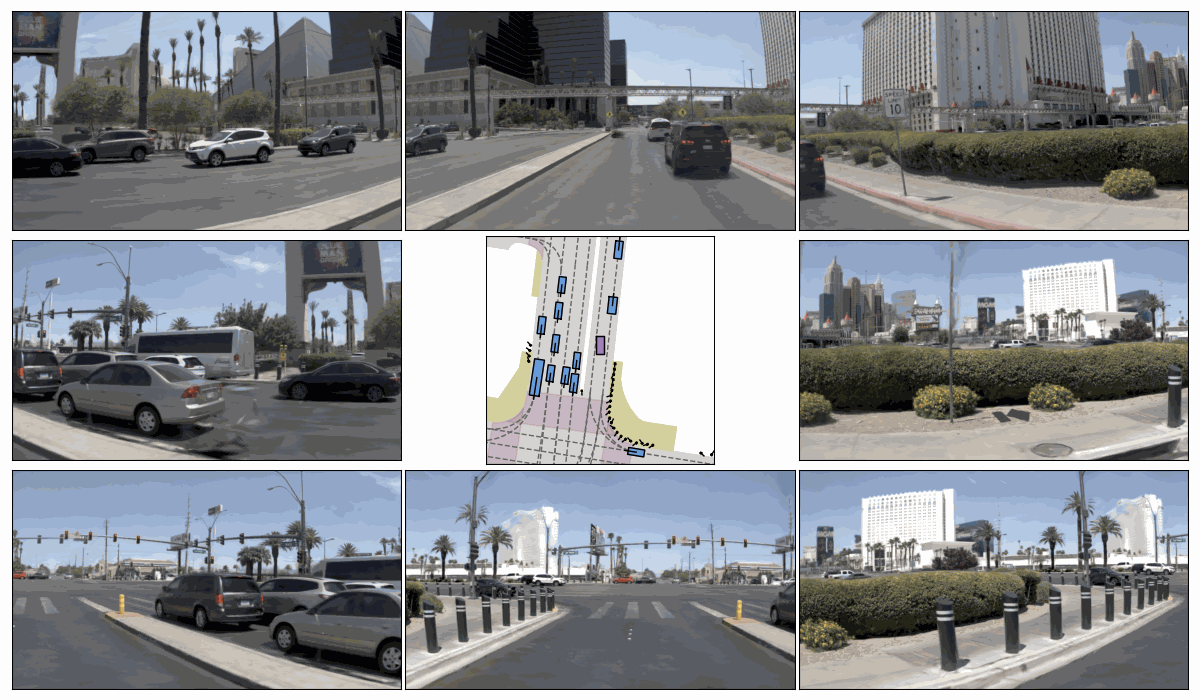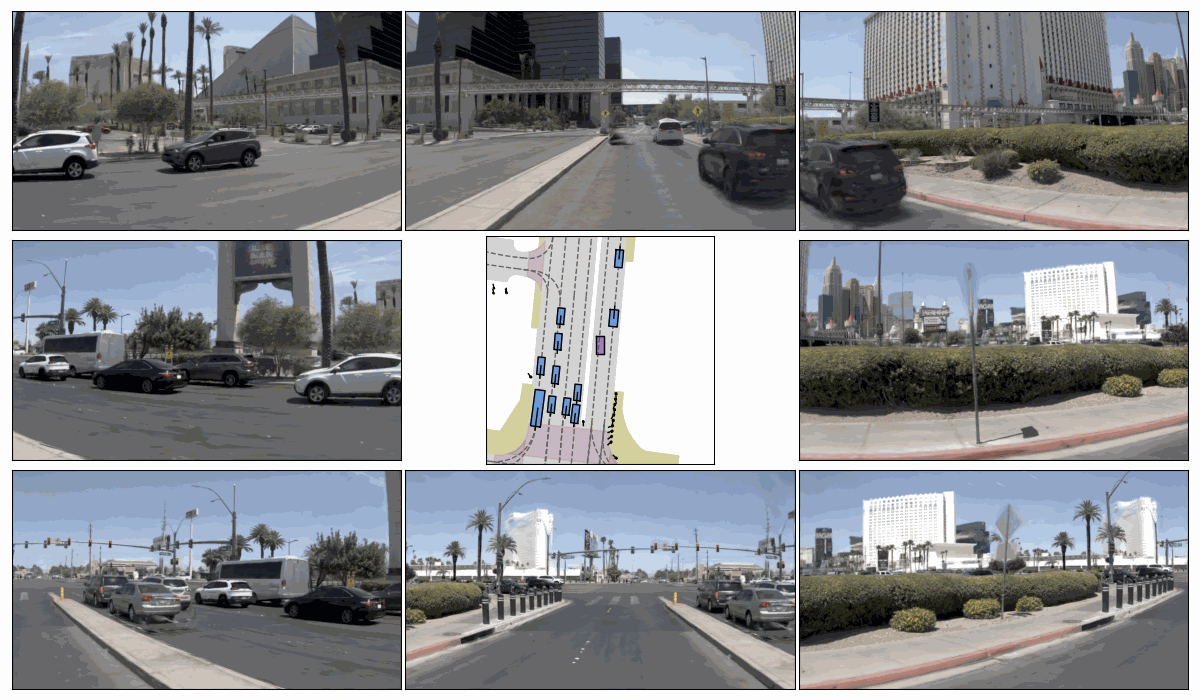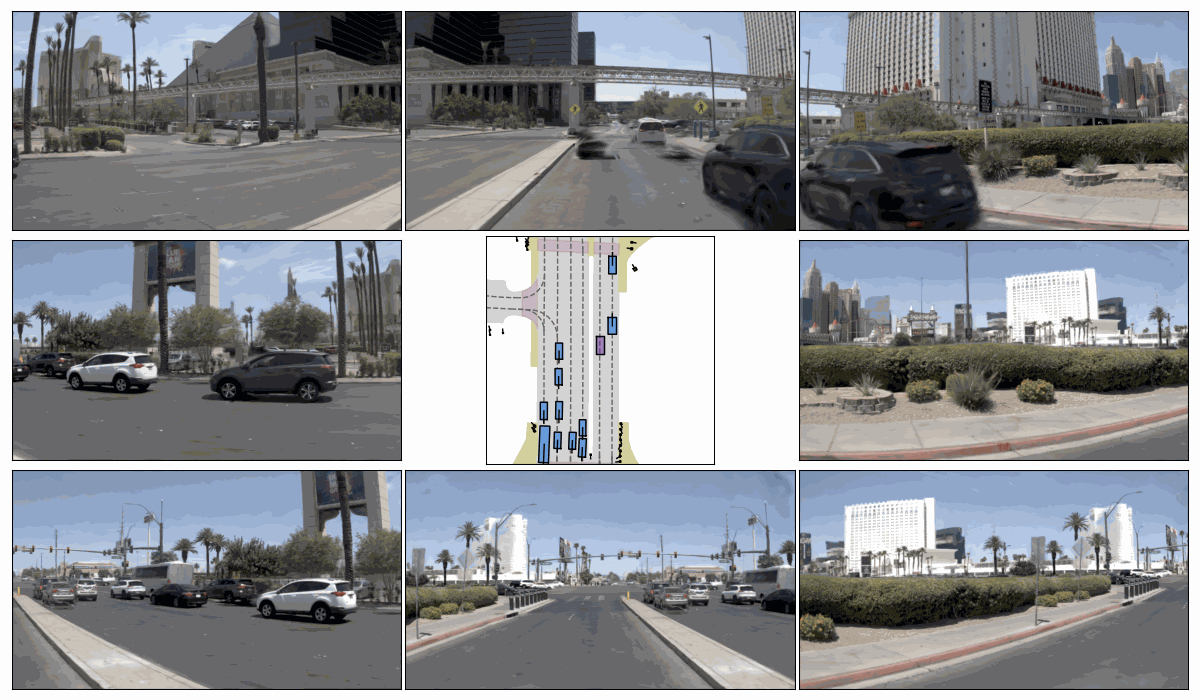 Sim. 3 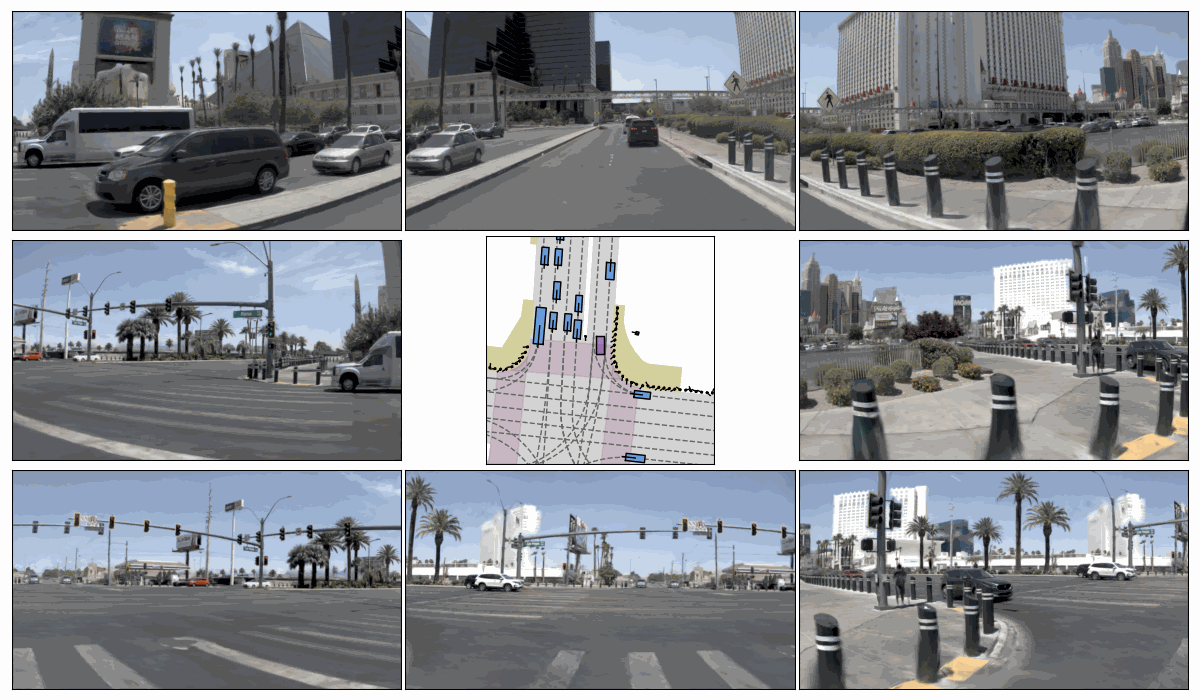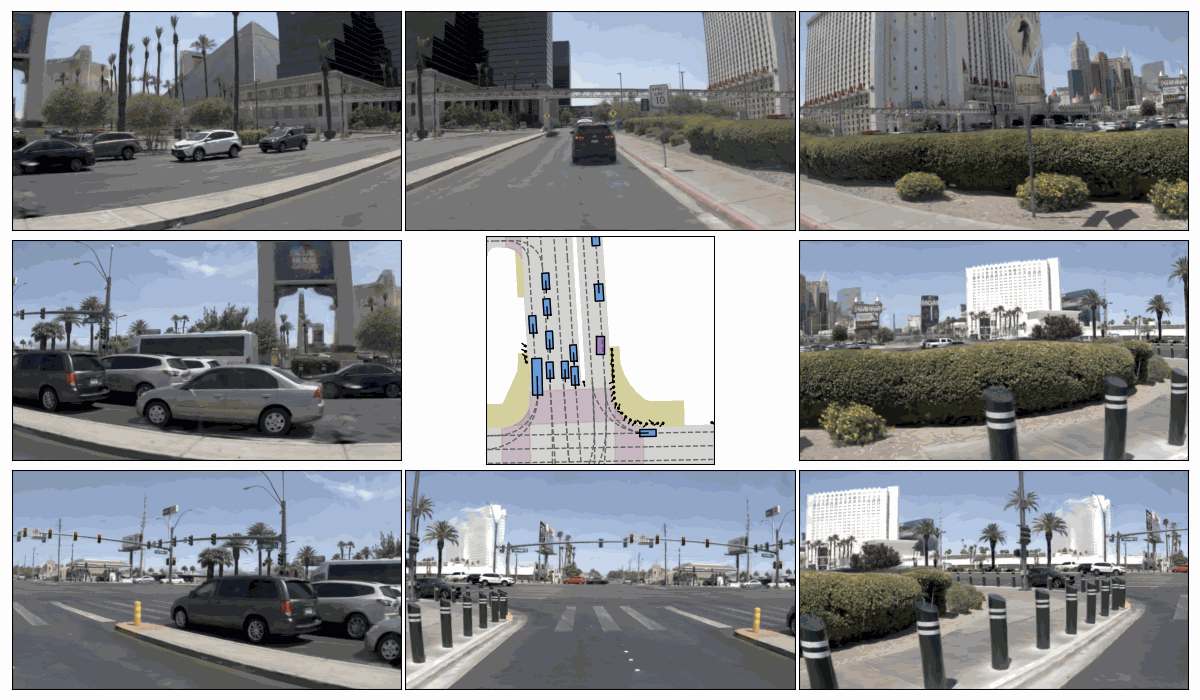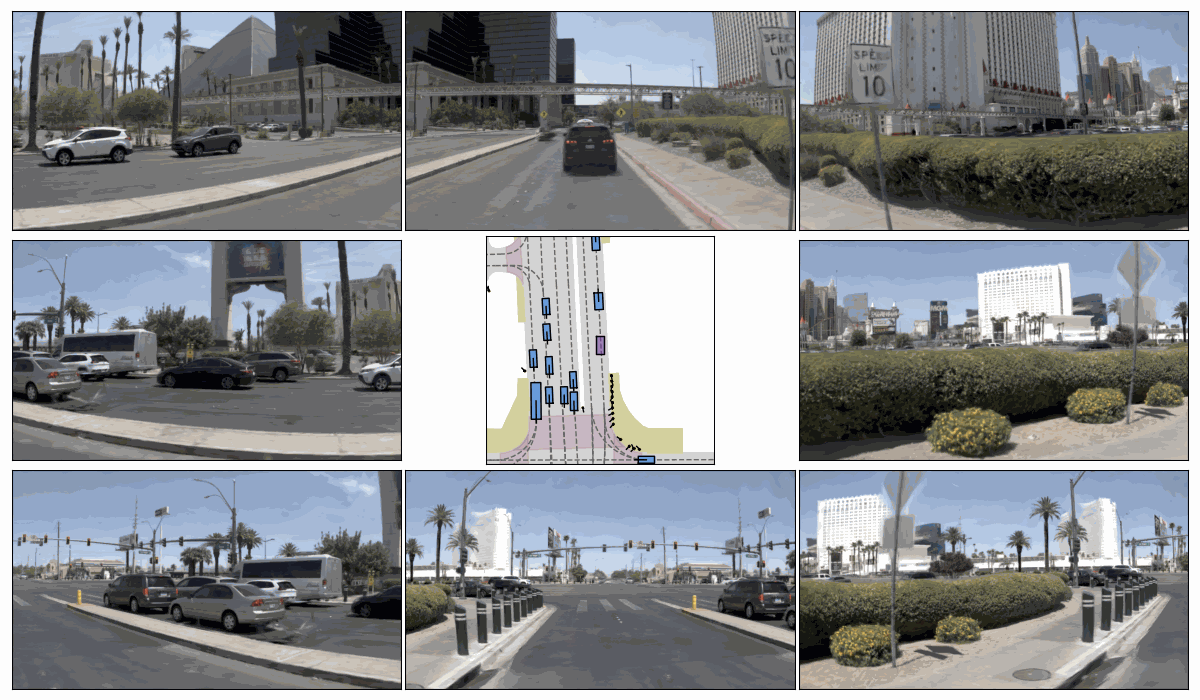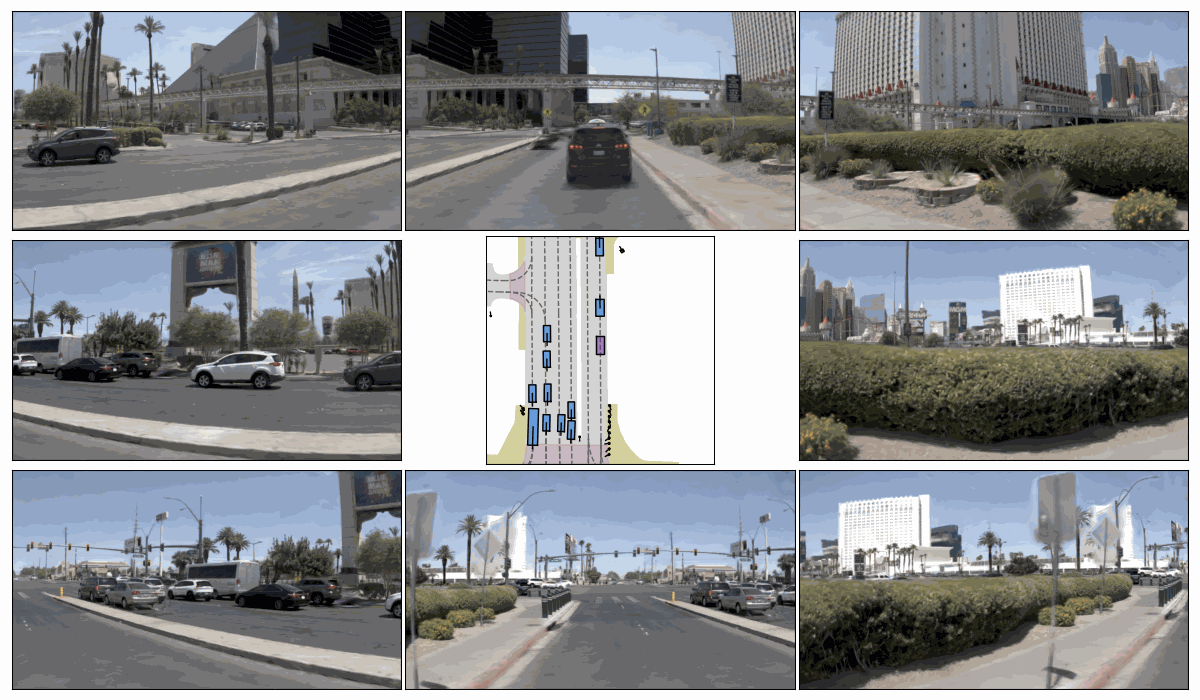
|
We provide a Script for moving the download simulation data to create the following structure.
navsim_workspace/
├── simscale/
├── exp/
└── dataset/
    ├── maps/
    ├── navsim_logs/
    │   ├── test/
    │   ├── trainval/
    │   ├── synthetic_reaction_pdm_v1.0-*/
    │   │   ├── [log]-00*.pkl
    │   │   └── ...
    │   └── synthetic_reaction_recovery_v1.0-*/
    ├── sensor_blobs/
    │   ├── test/
    │   ├── trainval/
    │   ├── synthetic_reaction_pdm_v1.0-*/
    │   │   └── [token]-00*/
    │   │       ├── CAM_B0/
    │   │       └── ...
    │   └── synthetic_reaction_recovery_v1.0-*/
    └── navhard_two_stage/
All content in this repository is under the Apache-2.0 license. The released data is based on nuPlan and is under the CC-BY-NC-SA 4.0 license.
If any parts of our paper and code help your research, please consider citing us and giving a star to our repository.
@article{tian2025simscale,
  title={SimScale: Learning to Drive via Real-World Simulation at Scale},
  author={Haochen Tian and Tianyu Li and Haochen Liu and Jiazhi Yang and Yihang Qiu and Guang Li and Junli Wang and Yinfeng Gao and Zhang Zhang and Liang Wang and Hangjun Ye and Tieniu Tan and Long Chen and Hongyang Li},
  journal={arXiv preprint arXiv:2511.23369},
  year={2025}
}