YODAS v3: A 1 Million Hour Dataset for the Next Generation of Open Voice AI Research 18 days ago • 36
Bagpiper Bagpiper: Solving Open-Ended Audio Tasks via Rich Captions Paper • 2602.05220 • Published Feb 5 Bagpiper-TTS: Natural Language Guided Universal Speech Synthesis Paper • 2606.22811 • Published Jun 22 espnet/bagpiper Any-to-Any • Updated Aug 2 espnet/bagpiper-sft Any-to-Any • Updated Aug 2
Bagpiper-TTS: Natural Language Guided Universal Speech Synthesis Paper • 2606.22811 • Published Jun 22
ARECHO Series espnet/arecho_base_v0 Updated Jun 13, 2025 • 10 espnet/arecho_scale_v0 Updated Jun 13, 2025 • 6 espnet/arecho_base_v0.1-large-decoder Updated Jun 13, 2025 • 3 espnet/arecho_scale_v0.1-large-decoder Updated Jun 13, 2025 • 10
UniVERSA vvwangvv/universa_ext-wavlm_base_urgent24_urgent25_multi-metric_noref Updated Jun 13, 2025 • 4 espnet/universa-wavlm_base_urgent24_multi-metric_noref Updated May 28, 2025 • 404 espnet/universa-wavlm_base_urgent24_multi-metric_audioref Updated May 30, 2025 • 8 espnet/universa-wavlm_base_urgent24_multi-metric_textref Updated May 30, 2025 • 7
OWSM: Fully Open Speech Recognition and Translation Models A collection of models related to the Open Whisper-style Speech Models (OWSM) project from CMU: https://www.wavlab.org/activities/2024/owsm/ espnet/owsm_ctc_v3.2_ft_1B Automatic Speech Recognition • Updated 25 days ago • 33 • 5 espnet/owsm_ctc_v3.1_1B Automatic Speech Recognition • Updated 25 days ago • 68 • 14 espnet/owsm_v3.1_ebf Automatic Speech Recognition • Updated 4 days ago • 130 • 17 espnet/owsm_v3.1_ebf_small Automatic Speech Recognition • Updated 4 days ago • 27 • 2
OWSM-CTC: Ultra-Fast Speech Foundation Models CTC-based models from the OWSM project, designed for fast non-autoregressive inference: https://www.wavlab.org/activities/2024/owsm/ espnet/owsm_ctc_v3.2_ft_1B Automatic Speech Recognition • Updated 25 days ago • 33 • 5 espnet/owsm_ctc_v3.1_1B Automatic Speech Recognition • Updated 25 days ago • 68 • 14
XEUS Model and Data Data and models used for EMNLP 2024 Best Paper "Towards Robust Speech Representation Learning for Thousands of Languages" espnet/mms_ulab_v2 Viewer • Updated Feb 4, 2025 • 20.7k • 920 • 28 espnet/wikitongues Viewer • Updated Jul 2, 2024 • 820 • 335 • 4 espnet/xeus Automatic Speech Recognition • Updated Jun 17, 2025 • 95 • 151 espnet/jesus_dramas Viewer • Updated Jul 2, 2024 • 397 • 174 • 4
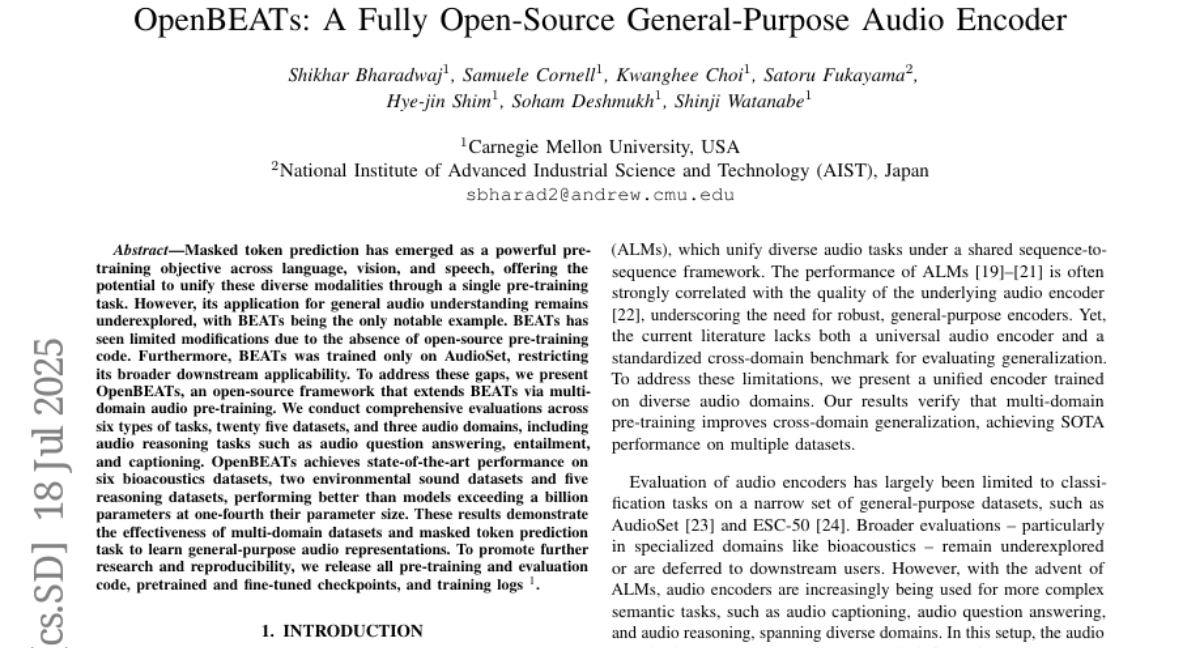
OpenBEATs OpenBEATs: A Fully Open-Source General-Purpose Audio Encoder OpenBEATs: A Fully Open-Source General-Purpose Audio Encoder Paper • 2507.14129 • Published Jul 18, 2025 • 13 shikhar7ssu/OpenBEATs-Large-i2 Updated Jul 21, 2025 • 9 • 2 shikhar7ssu/OpenBEATs-ICME Audio Classification • Updated Jan 26 • 7 shikhar7ssu/OpenBEATs-ICME-SOUND Audio Classification • Updated Jan 26 • 8
OpenBEATs: A Fully Open-Source General-Purpose Audio Encoder Paper • 2507.14129 • Published Jul 18, 2025 • 13
OpusLM The OpusLM collections espnet/OpusLM_7B_Anneal Updated 25 days ago • 41 • 2 espnet/OpusLM_1.7B_Anneal Updated 25 days ago • 48 • 1
Codec Survey - Pre-trained Models espnet/dac_16k_all_survey Audio-to-Audio • Updated 27 days ago • 29 espnet/dac_16k_music_survey Audio-to-Audio • Updated 27 days ago • 26 espnet/dac_44k_audio_single_survey Audio-to-Audio • Updated 27 days ago • 12 espnet/dac_16k_music_single_survey Audio-to-Audio • Updated 27 days ago • 10
OWLS: Scaling Laws for Speech Recognition and Translation 🦉 A suite of Whisper-style models from 250M to 18B parameters. Trained on up to 360K hours of data. 16k sampling rate. espnet/owls_4B_180K Automatic Speech Recognition • Updated May 3, 2025 • 10 • 5 espnet/owls_9B_180K Automatic Speech Recognition • Updated May 3, 2025 • 19 espnet/owls_05B_180K Automatic Speech Recognition • Updated May 3, 2025 • 10 espnet/owls_025B_180K Automatic Speech Recognition • Updated May 3, 2025 • 16
Neural Codecs Collection of neural codecs trained in ESPnet for speech tokenization espnet/dac_16k_music_survey Audio-to-Audio • Updated 27 days ago • 26 espnet/dac_44k_audio_single_survey Audio-to-Audio • Updated 27 days ago • 12 espnet/dac_16k_speech_single_survey Audio-to-Audio • Updated 27 days ago • 14 espnet/dac_16k_all_single_survey Audio-to-Audio • Updated 27 days ago • 9
Bagpiper Bagpiper: Solving Open-Ended Audio Tasks via Rich Captions Paper • 2602.05220 • Published Feb 5 Bagpiper-TTS: Natural Language Guided Universal Speech Synthesis Paper • 2606.22811 • Published Jun 22 espnet/bagpiper Any-to-Any • Updated Aug 2 espnet/bagpiper-sft Any-to-Any • Updated Aug 2
Bagpiper-TTS: Natural Language Guided Universal Speech Synthesis Paper • 2606.22811 • Published Jun 22
OpenBEATs OpenBEATs: A Fully Open-Source General-Purpose Audio Encoder OpenBEATs: A Fully Open-Source General-Purpose Audio Encoder Paper • 2507.14129 • Published Jul 18, 2025 • 13 shikhar7ssu/OpenBEATs-Large-i2 Updated Jul 21, 2025 • 9 • 2 shikhar7ssu/OpenBEATs-ICME Audio Classification • Updated Jan 26 • 7 shikhar7ssu/OpenBEATs-ICME-SOUND Audio Classification • Updated Jan 26 • 8
OpenBEATs: A Fully Open-Source General-Purpose Audio Encoder Paper • 2507.14129 • Published Jul 18, 2025 • 13
ARECHO Series espnet/arecho_base_v0 Updated Jun 13, 2025 • 10 espnet/arecho_scale_v0 Updated Jun 13, 2025 • 6 espnet/arecho_base_v0.1-large-decoder Updated Jun 13, 2025 • 3 espnet/arecho_scale_v0.1-large-decoder Updated Jun 13, 2025 • 10
OpusLM The OpusLM collections espnet/OpusLM_7B_Anneal Updated 25 days ago • 41 • 2 espnet/OpusLM_1.7B_Anneal Updated 25 days ago • 48 • 1
UniVERSA vvwangvv/universa_ext-wavlm_base_urgent24_urgent25_multi-metric_noref Updated Jun 13, 2025 • 4 espnet/universa-wavlm_base_urgent24_multi-metric_noref Updated May 28, 2025 • 404 espnet/universa-wavlm_base_urgent24_multi-metric_audioref Updated May 30, 2025 • 8 espnet/universa-wavlm_base_urgent24_multi-metric_textref Updated May 30, 2025 • 7
Codec Survey - Pre-trained Models espnet/dac_16k_all_survey Audio-to-Audio • Updated 27 days ago • 29 espnet/dac_16k_music_survey Audio-to-Audio • Updated 27 days ago • 26 espnet/dac_44k_audio_single_survey Audio-to-Audio • Updated 27 days ago • 12 espnet/dac_16k_music_single_survey Audio-to-Audio • Updated 27 days ago • 10
OWSM: Fully Open Speech Recognition and Translation Models A collection of models related to the Open Whisper-style Speech Models (OWSM) project from CMU: https://www.wavlab.org/activities/2024/owsm/ espnet/owsm_ctc_v3.2_ft_1B Automatic Speech Recognition • Updated 25 days ago • 33 • 5 espnet/owsm_ctc_v3.1_1B Automatic Speech Recognition • Updated 25 days ago • 68 • 14 espnet/owsm_v3.1_ebf Automatic Speech Recognition • Updated 4 days ago • 130 • 17 espnet/owsm_v3.1_ebf_small Automatic Speech Recognition • Updated 4 days ago • 27 • 2
OWLS: Scaling Laws for Speech Recognition and Translation 🦉 A suite of Whisper-style models from 250M to 18B parameters. Trained on up to 360K hours of data. 16k sampling rate. espnet/owls_4B_180K Automatic Speech Recognition • Updated May 3, 2025 • 10 • 5 espnet/owls_9B_180K Automatic Speech Recognition • Updated May 3, 2025 • 19 espnet/owls_05B_180K Automatic Speech Recognition • Updated May 3, 2025 • 10 espnet/owls_025B_180K Automatic Speech Recognition • Updated May 3, 2025 • 16
OWSM-CTC: Ultra-Fast Speech Foundation Models CTC-based models from the OWSM project, designed for fast non-autoregressive inference: https://www.wavlab.org/activities/2024/owsm/ espnet/owsm_ctc_v3.2_ft_1B Automatic Speech Recognition • Updated 25 days ago • 33 • 5 espnet/owsm_ctc_v3.1_1B Automatic Speech Recognition • Updated 25 days ago • 68 • 14
Neural Codecs Collection of neural codecs trained in ESPnet for speech tokenization espnet/dac_16k_music_survey Audio-to-Audio • Updated 27 days ago • 26 espnet/dac_44k_audio_single_survey Audio-to-Audio • Updated 27 days ago • 12 espnet/dac_16k_speech_single_survey Audio-to-Audio • Updated 27 days ago • 14 espnet/dac_16k_all_single_survey Audio-to-Audio • Updated 27 days ago • 9
XEUS Model and Data Data and models used for EMNLP 2024 Best Paper "Towards Robust Speech Representation Learning for Thousands of Languages" espnet/mms_ulab_v2 Viewer • Updated Feb 4, 2025 • 20.7k • 920 • 28 espnet/wikitongues Viewer • Updated Jul 2, 2024 • 820 • 335 • 4 espnet/xeus Automatic Speech Recognition • Updated Jun 17, 2025 • 95 • 151 espnet/jesus_dramas Viewer • Updated Jul 2, 2024 • 397 • 174 • 4